Articles
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
We ran an 'LLM proposes, code decides' auto-tuning loop on a daily WeChat newsletter for 40 days: 18 versions, 8 rollbacks. Three of those rollbacks overturned decisions a human had made, and one version whose knobs were identical to its parent still got rolled back. Using our real numbers, telling apart a 20% difference needs about 25,000 reads per version. At 60 reads a day, that is more than 400 days. This postmortem covers five reasons the flywheel never turned, and what actually moved the numbers.
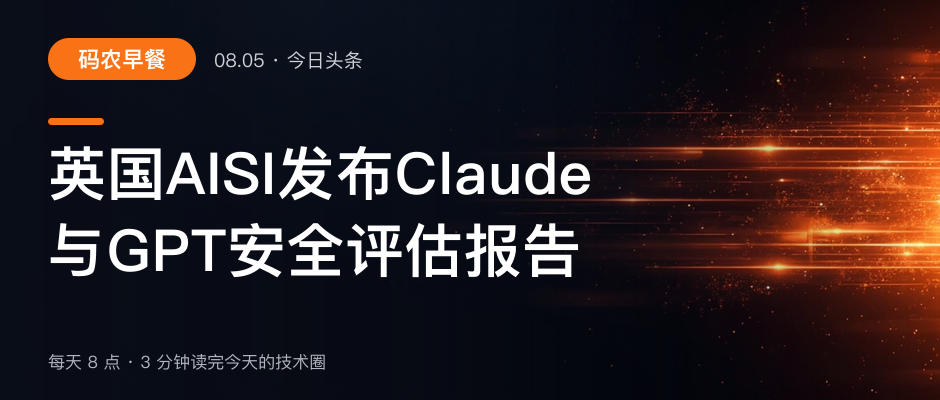
We automated our newsletter's daily WeChat cover: MiniMax image-01 renders a marketing-style background, an SVG text layer composites the headline, sharp crops to the exact 2.35:1 ratio, and Playwright drops it into the WeChat draft. The full postmortem covers why AI must never draw the title text, how one 'negative space' prompt word shoved the subject out of frame, and how word-splitting line breaks got fixed — with three real before/after images.