Articles
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
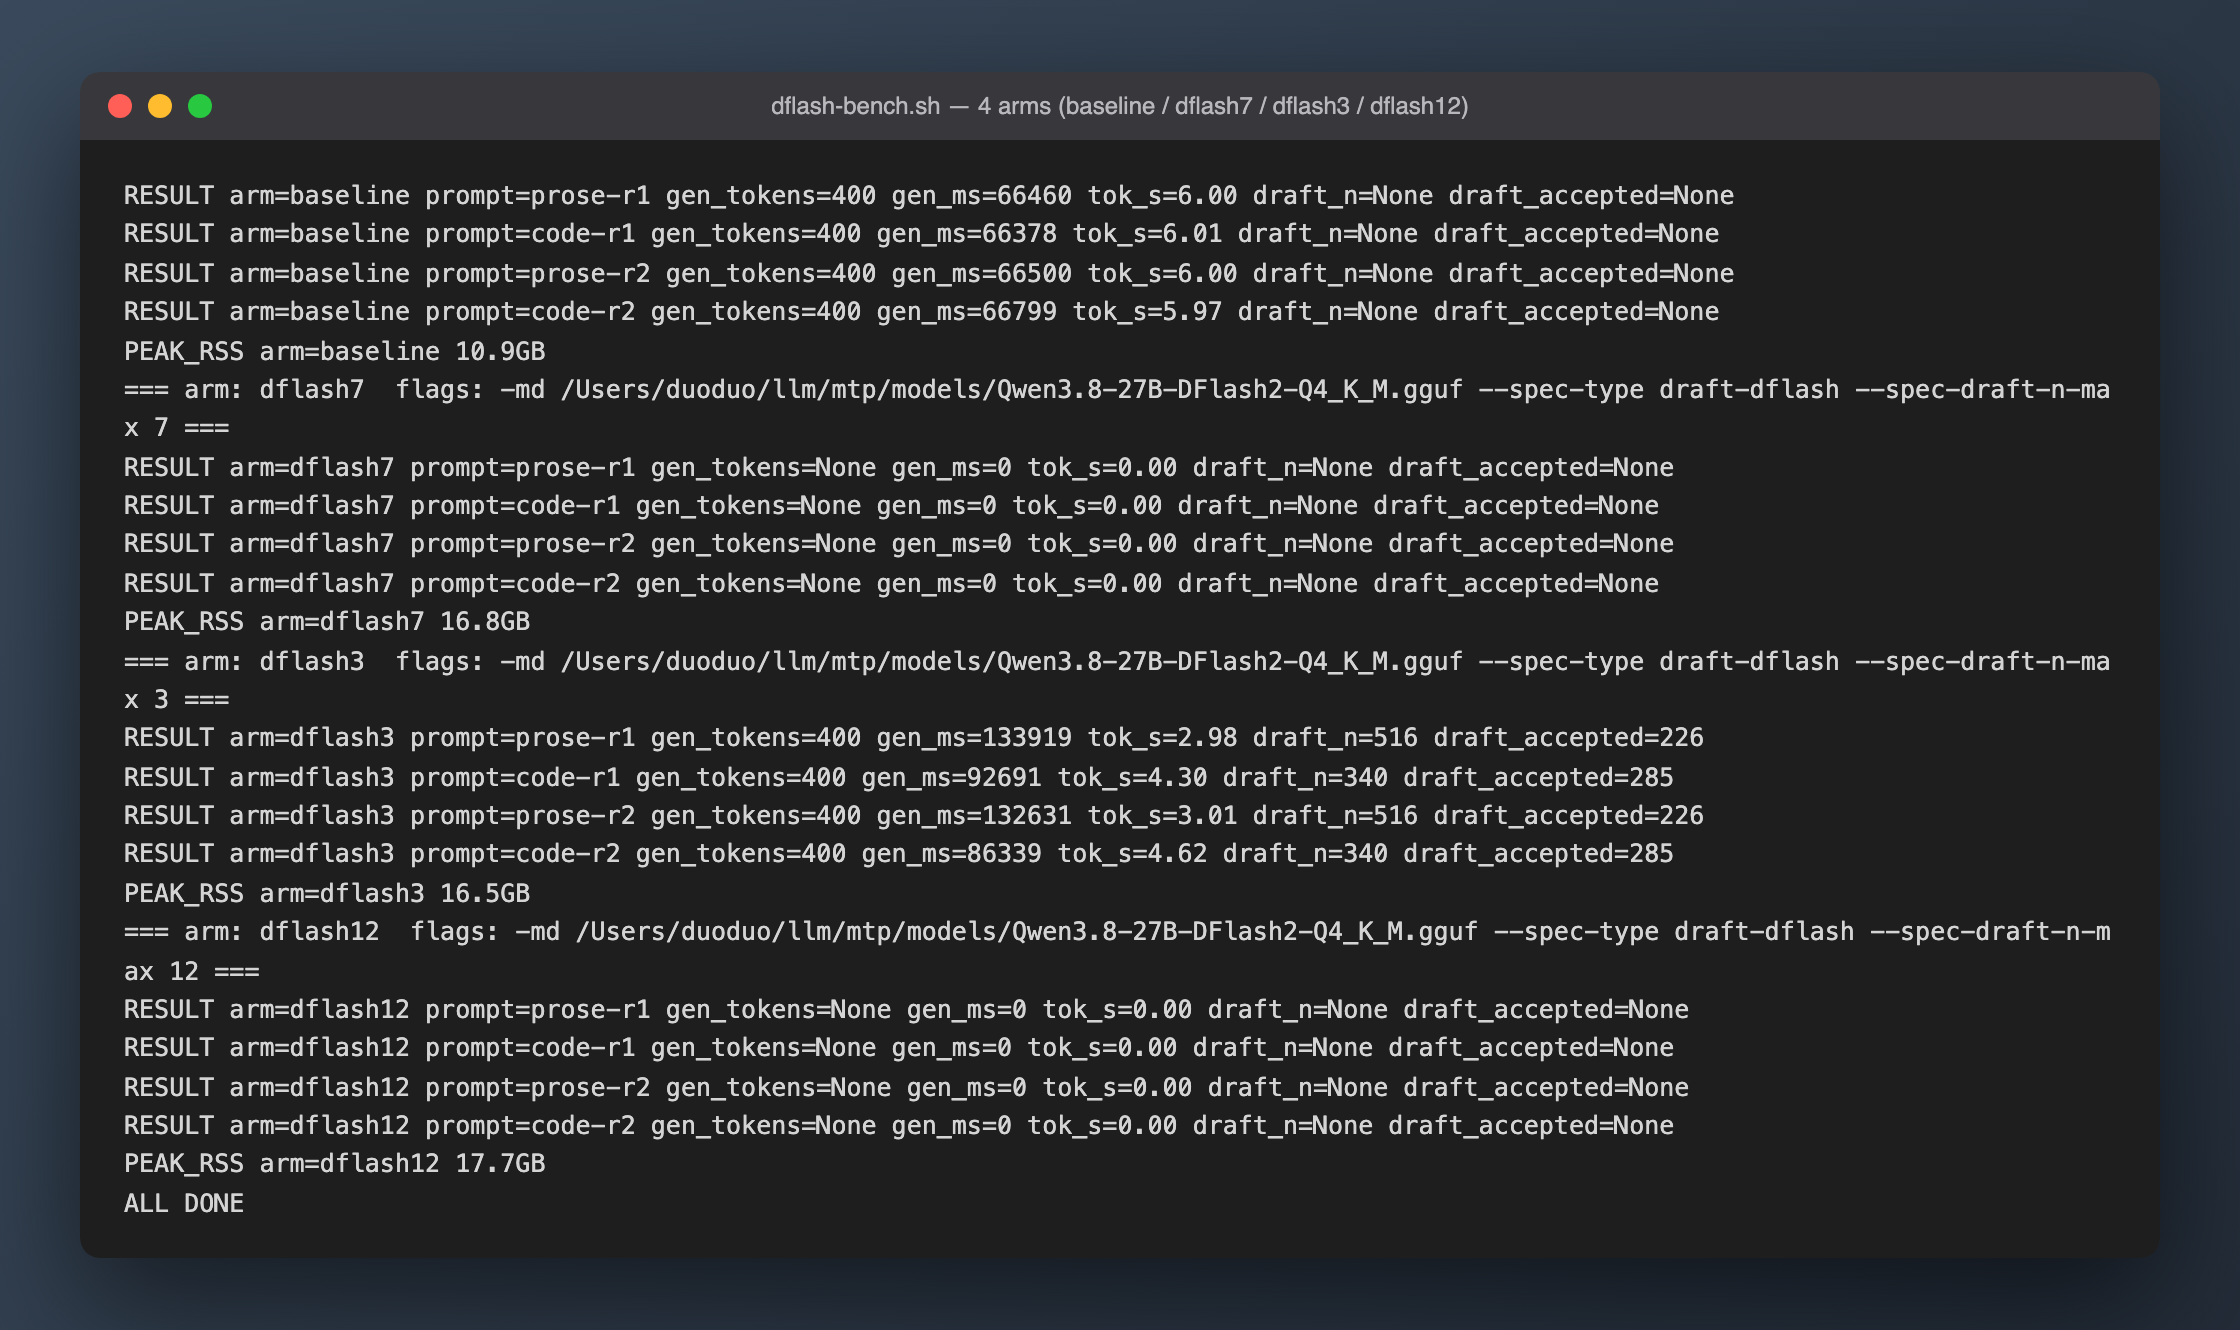
Part three of my speculative-decoding trilogy on a base Mac mini M4. llama.cpp merged DFlash 2 support with official GGUF drafts — and every configuration is a net slowdown. The README-recommended n-max 7 hits a reproducible Metal OOM on 24GB; the only stable setting cuts prose from 6.0 to 3.0 tok/s, and an 83.8% acceptance rate on code still loses 23%. Same algorithm, same machine, MLX gets 1.8–1.9x. The arithmetic shows why: 0.77s per speculative step loses even at 100% acceptance.
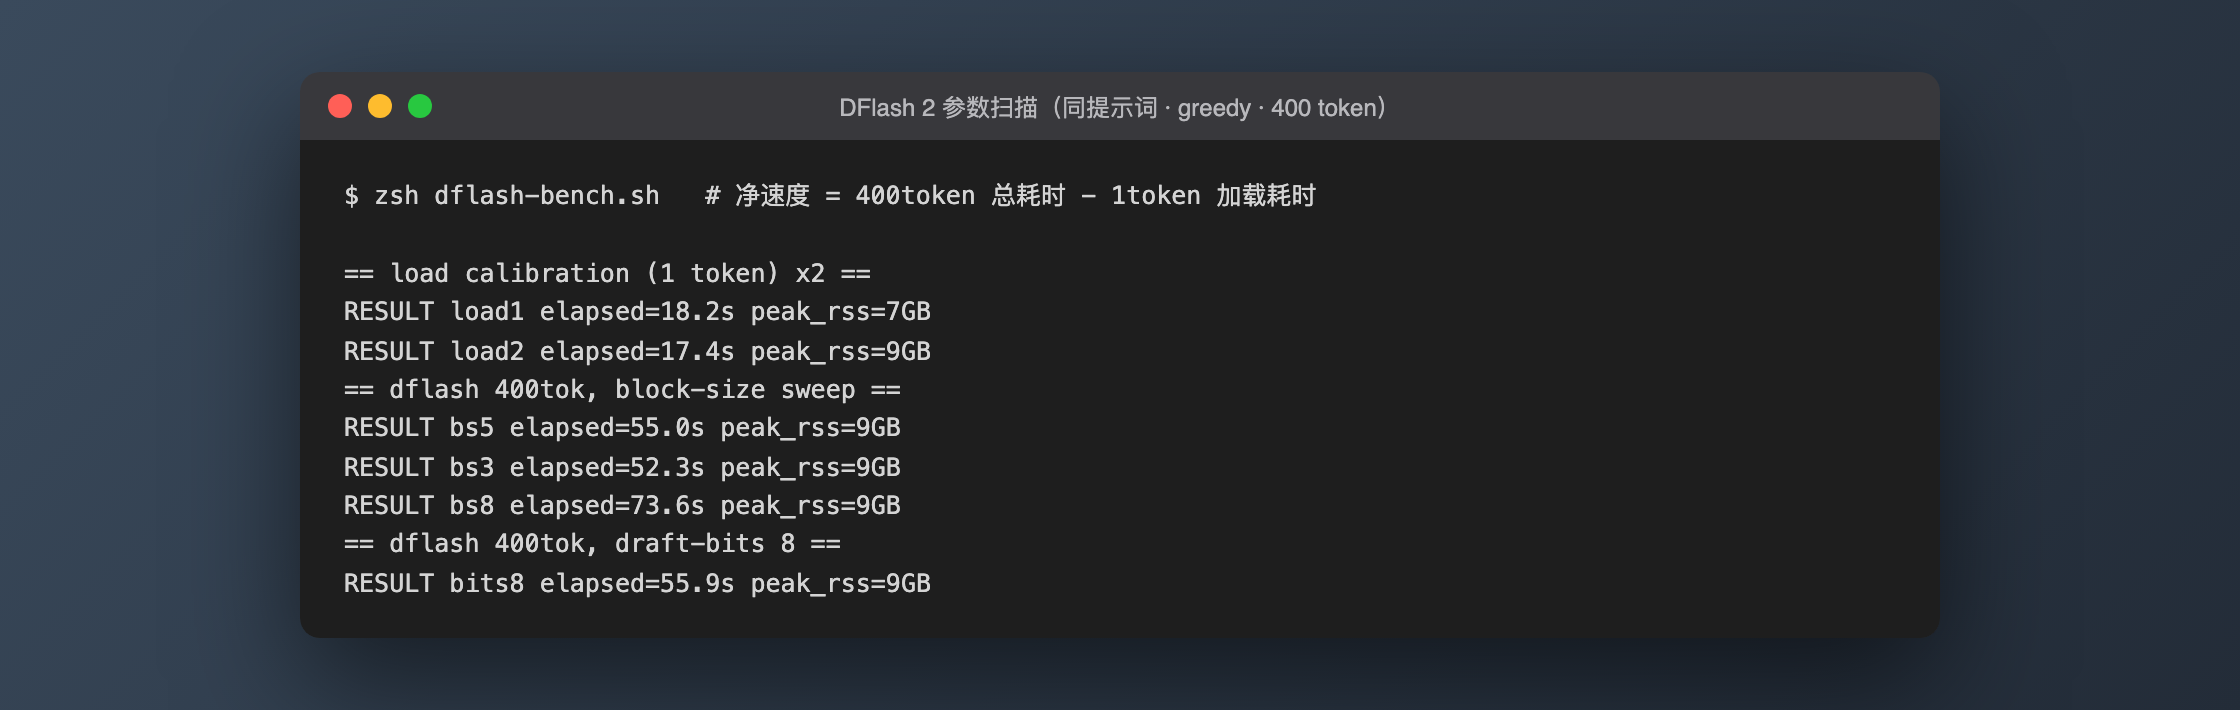
One week after DFlash 2 shipped, I got Qwen3.8-27B with speculative decoding fully working on a 24GB Mac mini M4: 6.5 tok/s to 11.7–12.2 tok/s at 4-bit, a stable 1.8–1.9x. This post covers the exact deployment commands, three controlled benchmark rounds, the GB-by-GB memory budget, and the three concrete reasons the official 2.7–3.4x number shrinks on consumer Apple Silicon. An Aug 29 retest adds a block-size and draft-precision sweep: block-size 8 collapses to 1.11x (the official cliff warning is real), block-size 3 beats the default, and an 8-bit draft loses to 4-bit.