Document Format Conversion Guide: Markdown, HTML, PDF & More
The modern developer and writer lives in a world of format fragmentation. You write documentation in Markdown, your client wants a PDF, your CMS accepts HTML, your legal team uses Word, and your static site generator expects frontmatter-annotated .md files. Every handoff between systems is a potential format mismatch — and every format mismatch is friction.
Understanding how document formats relate to each other, what survives conversion, and which tools handle each path best can save hours of manual reformatting. This guide covers the major conversion paths, with honest assessments of what each one preserves well and where it falls short.
Format Overview
| Format | Human Readability | Editability | Render Quality | Best For |
|---|---|---|---|---|
| Markdown | High (plain text) | Any text editor | Depends on renderer | Documentation, blogs, READMEs |
| HTML | Moderate (with tags) | Browser dev tools, code editor | Excellent (native web) | Web publishing, email templates |
| High (rendered) | Poor (locked layout) | Excellent (fixed) | Reports, invoices, print distribution | |
| DOCX | Low (binary) | Word, Google Docs, LibreOffice | Good (app-dependent) | Business documents, tracked changes |
| RST | High (plain text) | Any text editor | Good (Sphinx/docutils) | Python ecosystem documentation |
| LaTeX | Low (markup-heavy) | Specialized editors | Excellent (for math/print) | Academic papers, books |
Key Conversion Paths
Markdown → PDF
This is the most common conversion request: you've written documentation or a report in Markdown and need to share it as a professional PDF.
Browser print method is the simplest approach. Render your Markdown to HTML (using any Markdown previewer), then use the browser's Print dialog with "Save as PDF" selected. The output quality depends entirely on the CSS applied to the rendered HTML. Without explicit print CSS, you may get broken page breaks and unstyled output.
For better results, define print-specific CSS:
@media print {
  pre, blockquote { page-break-inside: avoid; }
  h1, h2, h3 { page-break-after: avoid; }
  body { font-size: 12pt; line-height: 1.5; }
}
Dedicated CLI tools offer more control:
# Using Pandoc with a LaTeX engine (best quality)
pandoc input.md -o output.pdf --pdf-engine=xelatex

# Using wkhtmltopdf (HTML-based rendering)
pandoc input.md -o temp.html && wkhtmltopdf temp.html output.pdf

# Using md-to-pdf (npm package, CSS customizable)
npx md-to-pdf input.md
Pandoc with a LaTeX engine produces the highest-quality PDFs and handles mathematical notation correctly. The trade-off is that you need LaTeX installed (~3GB), and tables require careful formatting.
Online tools: MagicTools Markdown Editor, Dillinger.io, and StackEdit all support direct PDF export for occasional use without any local installation.
Styling considerations: Syntax-highlighted code blocks, custom fonts, and page headers/footers require either a custom CSS file (for HTML-based rendering) or a Pandoc template (for LaTeX-based rendering). Plan for this overhead before committing to a Markdown → PDF workflow at scale.
Markdown → HTML
This path powers most static site generators and is arguably the most important conversion in the modern web stack.
Static site generators (Hugo, Jekyll, Eleventy, Astro) handle this automatically: you drop .md files in a content directory, run a build command, and get an optimized HTML site. This is the recommended approach for anything that will be published regularly.
For embedding Markdown in existing web pages without a full SSG, several libraries handle the conversion:
// Using the 'marked' library (client-side or Node.js)
import { marked } from 'marked';
const html = marked.parse(markdownContent);

// Using 'unified' pipeline (server-side, more extensible)
import { unified } from 'unified';
import remarkParse from 'remark-parse';
import remarkRehype from 'remark-rehype';
import rehypeStringify from 'rehype-stringify';

const result = await unified()
  .use(remarkParse)
  .use(remarkRehype)
  .use(rehypeStringify)
  .process(markdownContent);
For email templates: Markdown → HTML is appealing for email because it lets you write content without wrestling with HTML tables. However, email clients strip many HTML elements and most CSS. Run the output through a tool like Juice to inline all CSS, and test with Litmus before sending at scale.
HTML → Markdown
This conversion is less predictable than the reverse. HTML supports far more formatting options than Markdown, so some information is inevitably lost or simplified.
Blog migration is the primary use case. If you're moving from WordPress or Ghost to a static site generator, you need to convert hundreds of HTML posts to Markdown. The workflow:
- Export posts as HTML (WordPress has a built-in exporter)
- Use Pandoc for bulk conversion:
# Convert a single file pandoc input.html -o output.md # Batch convert all HTML files in a directory for file in *.html; do pandoc "$file" -o "${file%.html}.md" done - Review and fix: tables, custom shortcodes, and embedded media will need manual attention
MagicTools HTML to Markdown is the fastest option for individual pages — paste HTML or enter a URL, get clean Markdown immediately. Ideal for converting web-scraped content or individual articles.
What gets lost: <div> and <span> styling, CSS classes, colspan/rowspan in tables, inline style attributes, and embedded <iframe> content. If your HTML relied heavily on CSS classes for visual structure, the Markdown output will be structurally accurate but visually stripped down.
PDF → Text/Markdown
This is the hardest conversion because PDFs are presentation-optimized, not content-optimized. The internal structure of a PDF is a collection of positioned text elements — it doesn't preserve the semantic meaning of headings, paragraphs, or lists.
When the PDF contains real text (not scanned images), extraction tools work reasonably well:
# Using pdftotext (part of poppler-utils)
pdftotext input.pdf output.txt

# Using Pandoc (limited PDF support)
pandoc input.pdf -o output.md
When the PDF is a scanned image, you need OCR (Optical Character Recognition):
- Tesseract (open source):
tesseract input.pdf output -l eng - Adobe Acrobat (paid): Best commercial OCR quality
- Google Drive: Upload a PDF, open with Google Docs — it performs OCR automatically (free)
Expect significant cleanup: OCR output typically requires fixing hyphenation breaks, removing page headers/footers that repeat, re-establishing paragraph structure, and manually identifying headings. For a 50-page scanned document, plan 2–4 hours of cleanup regardless of OCR quality.
When to use manual transcription: If the PDF contains complex layouts (multi-column, sidebars, tables with merged cells) or mathematical notation, OCR will produce unusable output. Manual transcription or a professional conversion service is often more cost-effective than cleaning up bad OCR output.
Word/DOCX → Markdown
DOCX is structurally richer than HTML or Markdown, but the conversion is surprisingly reliable for straightforward documents.
Pandoc is the go-to tool:
pandoc input.docx -o output.md --extract-media=./images
The --extract-media flag saves embedded images to a folder and creates relative references to them in the Markdown output.
What survives conversion well:
- Headings (H1–H6)
- Bold, italic, strikethrough
- Unordered and ordered lists
- Code blocks (if formatted with a monospace style)
- Hyperlinks
What needs manual attention:
- Tables with merged cells (converted to simple tables or lost)
- Text boxes and callouts (often dropped entirely)
- Custom paragraph styles (normalized to basic formatting)
- Comments and tracked changes (usually stripped)
- Footnotes (converted to inline references in some renderers)
Online converters: CloudConvert, Word2Markdown, and Pandoc's web interface all handle DOCX → Markdown. For occasional one-off conversions, these are faster than setting up Pandoc locally.
Conversion Quality: What to Check
After any conversion, verify these specific elements before using the output:
| Element | Common Issues | How to Check |
|---|---|---|
| Tables | Alignment lost, merged cells broken | Review in Markdown preview |
| Images | Broken paths, missing alt text | Check rendered output visually |
| Code blocks | Language hints missing, indentation broken | Test with syntax highlighter |
| Links | Relative vs absolute URL mismatches | Click-test a sample |
| Headings | Hierarchy flattened or skipped levels | Check H1–H3 nesting |
| Special characters | Encoding issues with non-ASCII | Search for replacement characters (?) |
Real-World Workflow: WordPress → Hugo Migration
Here's a concrete end-to-end example. A technical blog with 200 posts needs to migrate from WordPress to Hugo.
Step 1 — Export from WordPress Use the WordPress Exporter to download an XML file. Then use wordpress-to-hugo-exporter to convert the XML directly to Hugo-formatted Markdown files with frontmatter.
Step 2 — Batch convert and review Run the exporter script. Expect ~85% of posts to convert cleanly. The remaining 15% will have issues — typically shortcode plugins, embedded tweets/YouTube, or heavy custom HTML in specific posts.
Step 3 — Handle images
Download all media from the WordPress media library. Update image paths in Markdown files (WordPress uses absolute URLs; Hugo expects paths relative to the static/ directory).
Step 4 — Fix shortcodes
WordPress shortcodes like [caption] or [gallery] have no Markdown equivalent. Either replace them with standard Markdown image syntax or use Hugo shortcodes for complex cases.
Step 5 — Verify in Hugo
Run hugo server, check 20–30 posts manually, run a broken link checker (linkchecker or htmlproofer), and verify all images load correctly.
Total migration effort for 200 posts: approximately 8–16 hours depending on content complexity.
Hands-on test: one real file through each of the 8 directions
Background
The quality table above is judgment, not measurement. This site runs its own file converter on Gotenberg (LibreOffice + Chromium) with eight directions, and until today I had never pushed a file with Chinese text, a table and an embedded image through every one of them, nor timed a single conversion, nor checked whether the table and the picture survived. This section closes that gap.
Analysis
"It converts" and "it converts correctly" have to be measured separately:
- Latency has one honest number: end-to-end time from my machine to a complete PDF (curl's
time_total), which includes upload, queueing, rendering and download. Gotenberg does not expose its internal render time, so I neither split it out nor estimate it. - Text fidelity uses poppler's
pdftotextto pull the text back out, strips all whitespace, and compares it character by character against the source (Pythondifflibratio). On top of that I count how many of 6 unique marker tokens (ZX7Q-4K,磁悬浮,3.1415926and so on) and 24 table cells came back. Garbled CJK, dropped characters or a vanished table all show up as a lower score. - Structure and visuals:
pdfinfofor page count,pdftoppmto render a PNG, the non-white pixel ratio to catch blank pages, and a count of the two colors used only in the test figure (blue bars, green circle) to confirm the image made it into the PDF. - The in-browser directions (pdf-to-jpg / pdf-to-png) also need proof that the file never left the browser: intercept every non-GET request the page makes and require the count to be zero.
Approach and what I ruled out
- Hit the production endpoint; do not run the stack locally. This Mac has no Docker and Homebrew has no Gotenberg formula, so the LibreOffice + Chromium container cannot start here.
npm run devwould connect to the production database and write a counter row per conversion. Production is what users actually hit anyway. The cost is that network time is in every number, which I say out loud below. - Generate the sources with
uvand python-docx / python-pptx / openpyxl / Pillow rather than downloading samples. The three Office files share the same content: four Chinese paragraphs, a marker line, a 6×4 table and a 640×320 figure drawn with Pillow. HTML and Markdown are hand-written with the same paragraphs and table; Markdown adds a code block. Saving from Word or PowerPoint was out: not installed, and hand-made files are not reproducible. - The five server-side directions go through curl to
POST /api/convert?direction=<id>, field namefile, with a browser User-Agent (a bare curl UA gets a 403) and-L. Anonymous quota is 10 per IP per day, successes and failures both count, and theX-Quota-Usedresponse header tells you where you stand. Budget: one call per direction, two extra for the slowest (markdown-to-pdf) and one extra for word-to-pdf to see jitter, one held in reserve, zero spent on probing the request format. - pdf-to-jpg / pdf-to-png are driven through the live tool page with Playwright:
setInputFiles, click Convert, wait for the result images, then pull the blob images back to disk. The input is the PDF that markdown-to-pdf produced minutes earlier. - merge-pdf goes through
/api/pdf/process(pdf-lib), anonymous, outside the conversion quota, merging the docx, pptx and xlsx outputs into one file.
Procedure
Generate the sources:
uv venv tmp/2026-09-12-doc-convert/.venv
uv pip install python-docx python-pptx openpyxl pillow
.venv/bin/python make-sources.py
# figure.png 2024 B · sample.docx 39149 B · sample.pptx 31732 B
# sample.xlsx 8321 B · sample.html 1618 B · sample.md 1152 B
Each server-side call looks like this (swap direction and file):
curl -sL -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) ... Chrome/150.0.0.0 Safari/537.36' \
  -D out/markdown-to-pdf-1.hdr -F 'file=@src/sample.md' -o out/markdown-to-pdf-1.pdf \
  -w '{"http":%{http_code},"time_total":%{time_total},"time_starttransfer":%{time_starttransfer}}' \
  'https://tools.cooconsbit.com/api/convert?direction=markdown-to-pdf'
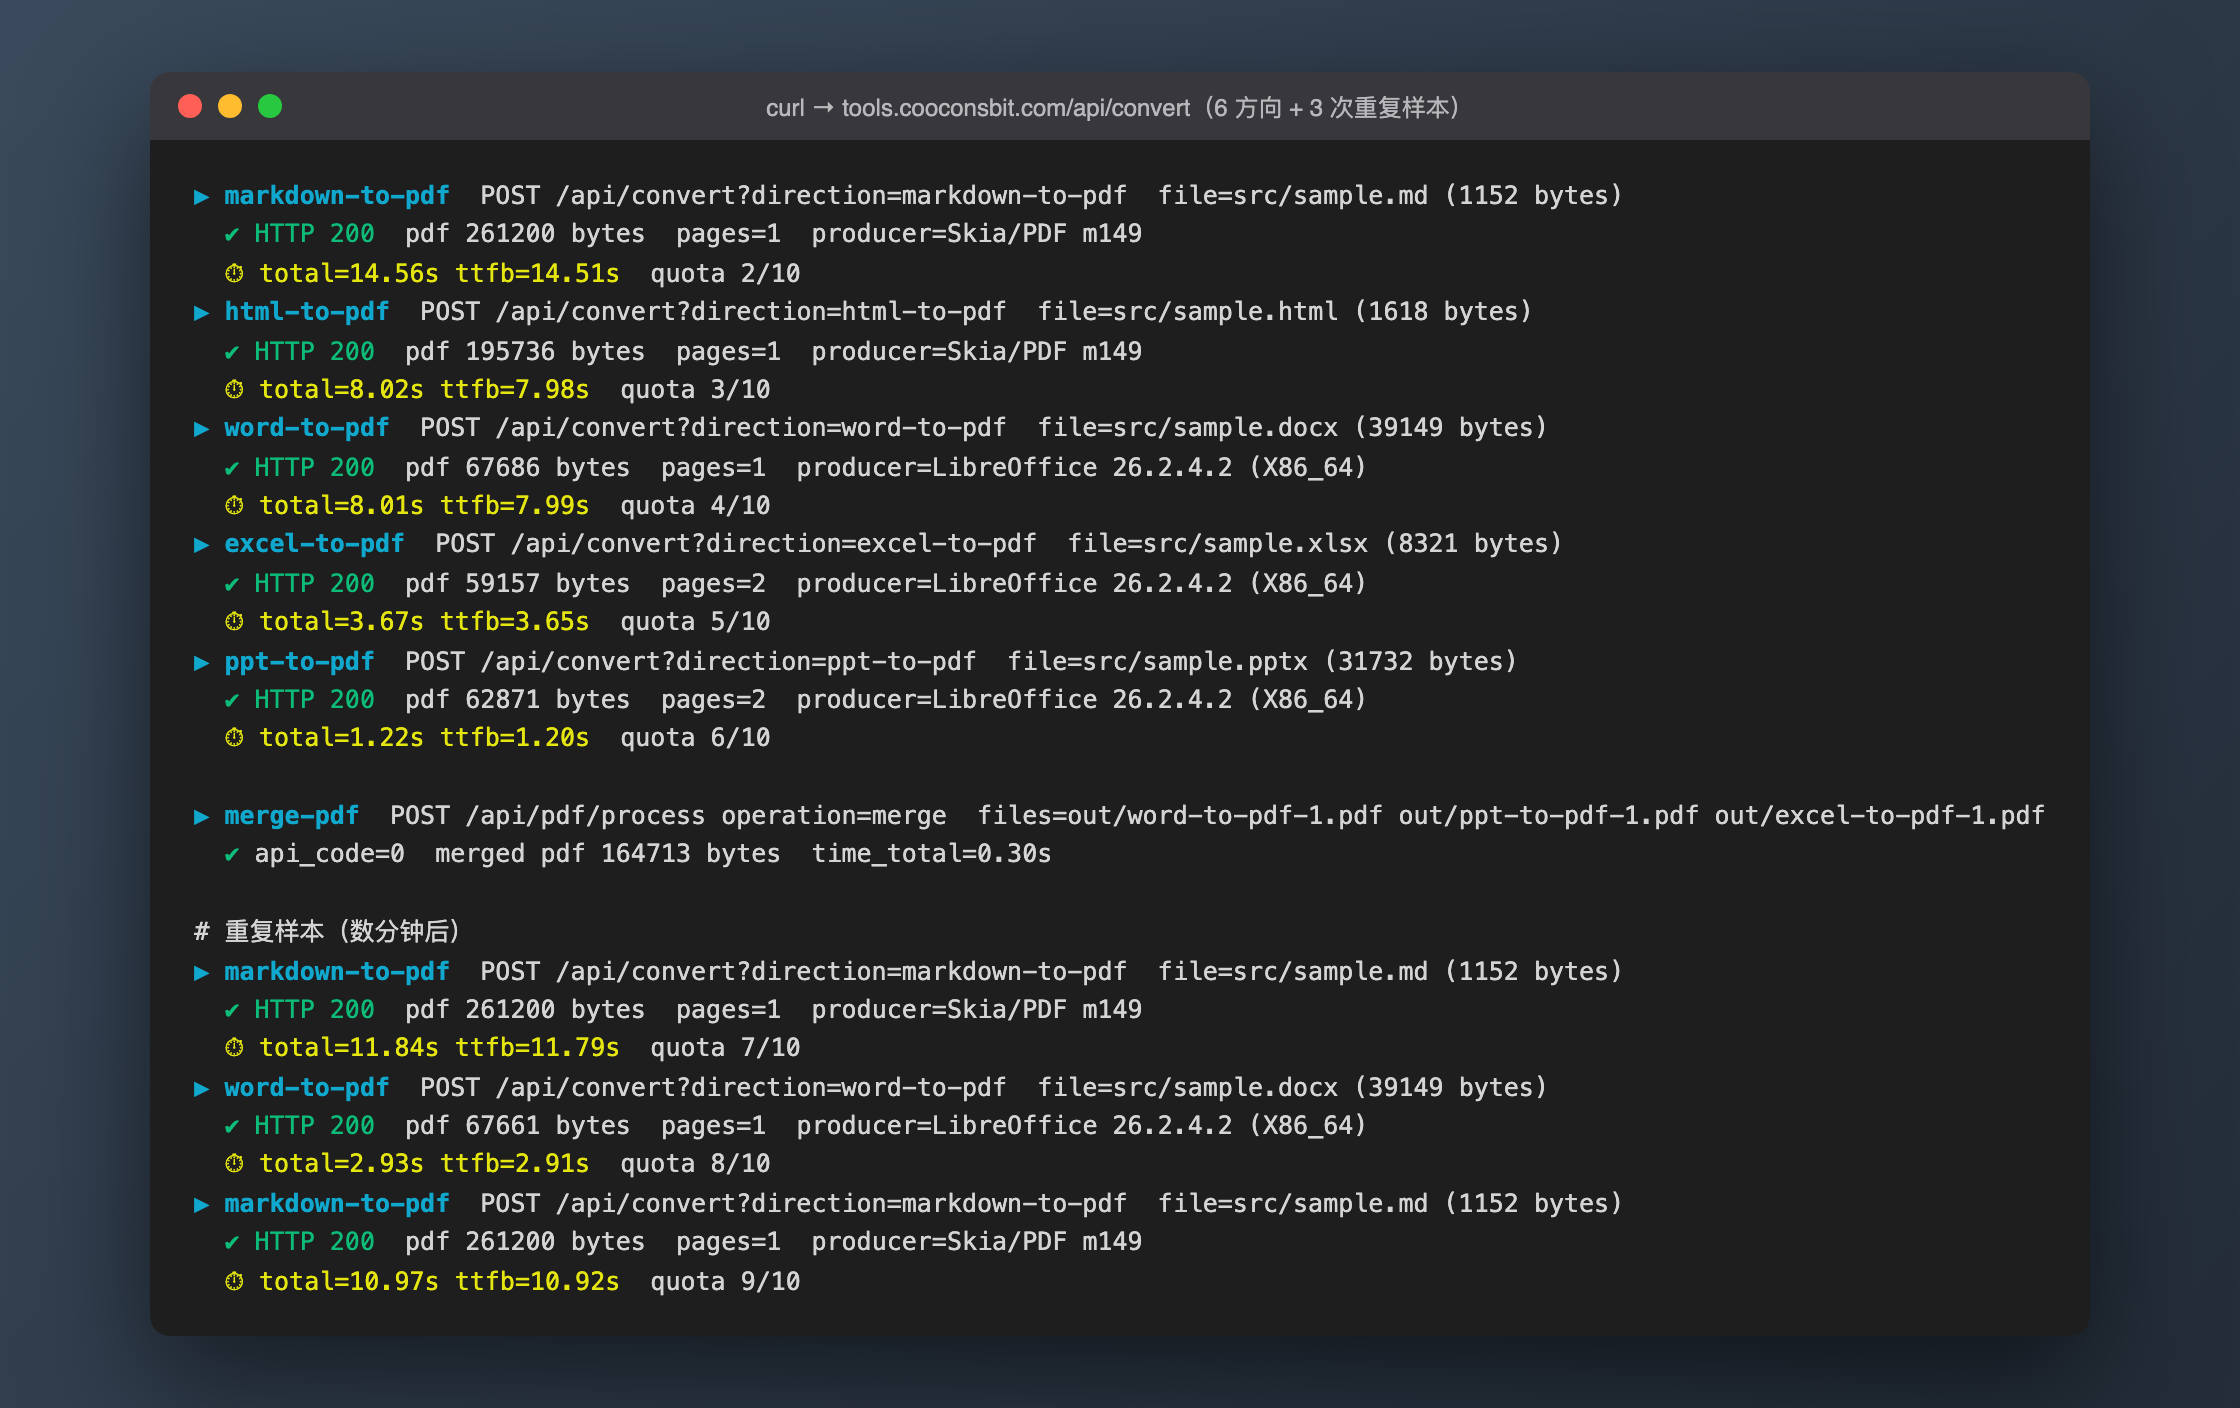
Six server-side directions plus three repeat samples in one go, all HTTP 200, quota moving from 2/10 to 9/10:
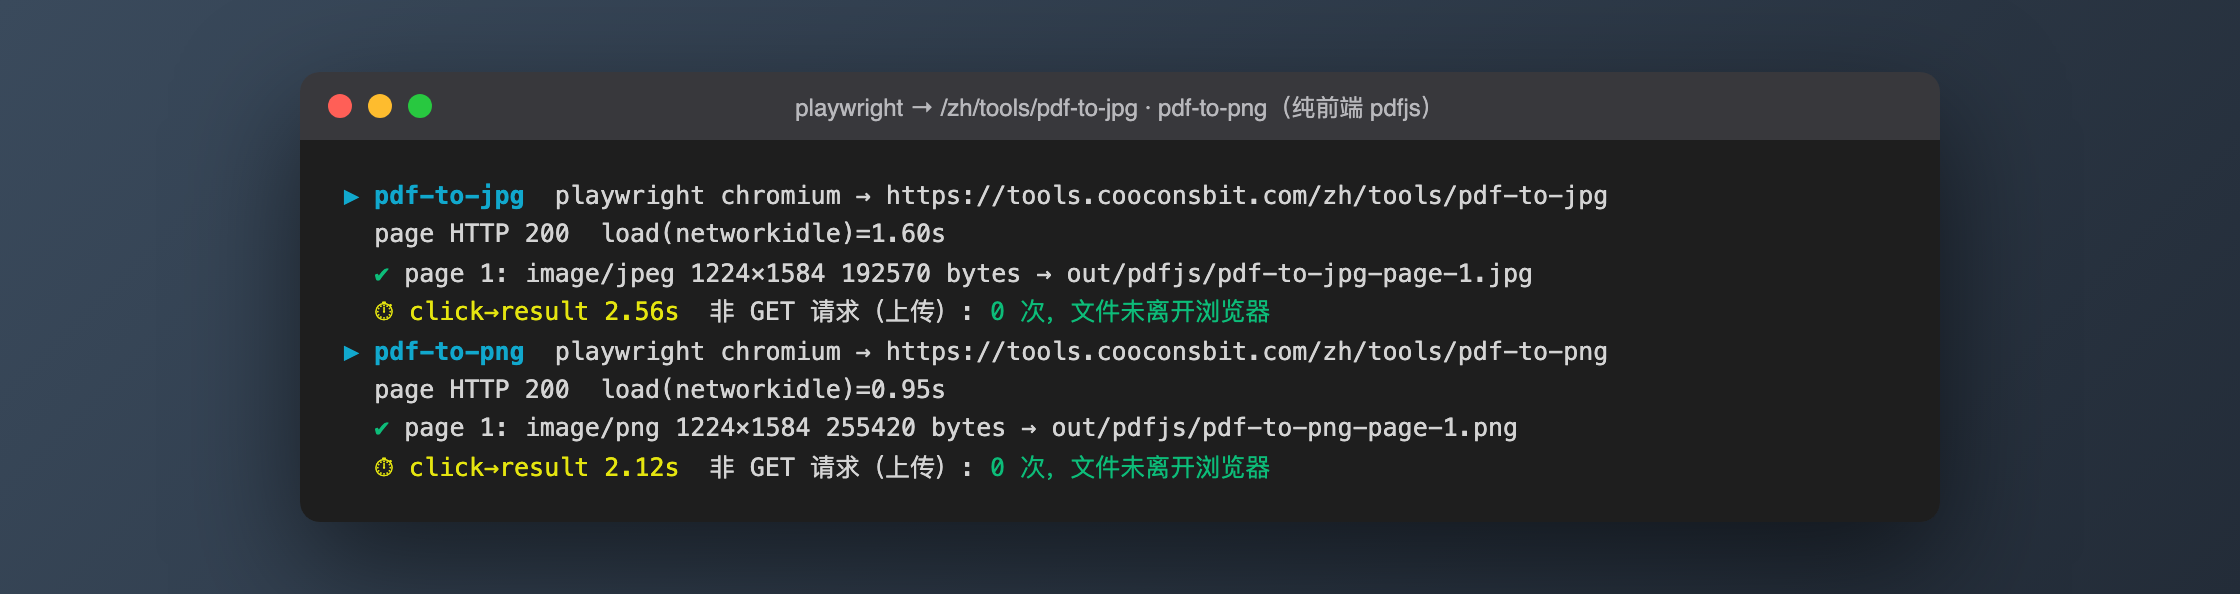
The two browser-side directions, driven by Playwright. The green "100% local" banner on the page is not decoration: the interceptor counted zero non-GET requests.
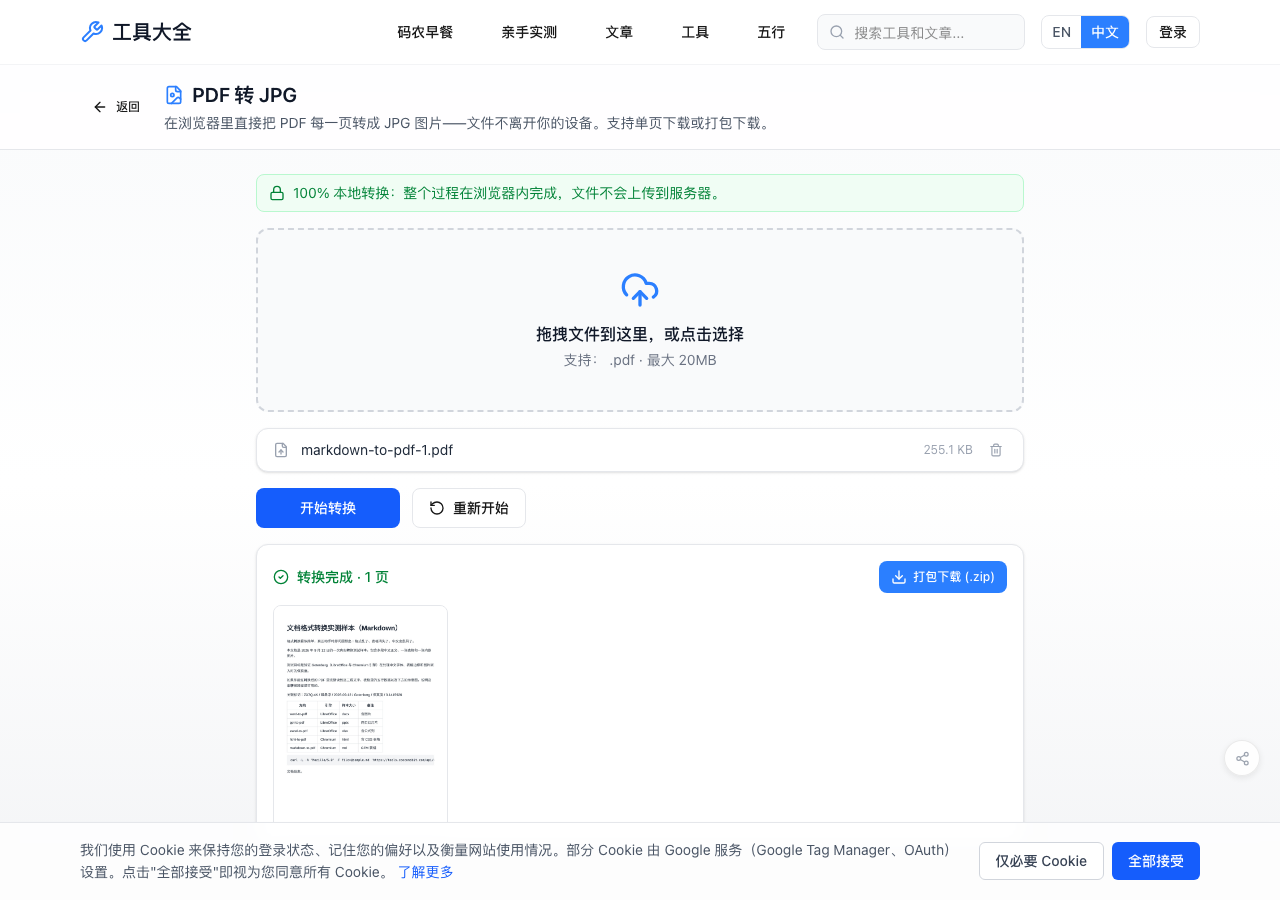
The actual page after Playwright clicked Convert:
Results
Latency (my machine to the production endpoint, network included; DNS sent the requests to the Beijing host):
| Direction | Engine | Samples | Time | Output |
|---|---|---|---|---|
| markdown-to-pdf | Chromium | 3 | 10.97 / 11.84 / 14.56 s (min / median / max) | 1 page, 261,200 B |
| html-to-pdf | Chromium | 1 | 8.02 s | 1 page, 195,736 B |
| word-to-pdf | LibreOffice | 2 | 2.93 / 8.01 s | 1 page, 67,686 B |
| excel-to-pdf | LibreOffice | 1 | 3.67 s | 2 pages, 59,157 B |
| ppt-to-pdf | LibreOffice | 1 | 1.22 s | 2 pages, 62,871 B |
| merge-pdf | pdf-lib | 1 | 0.30 s | 5 pages, 164,713 B |
| pdf-to-jpg | in-browser pdf.js | 1 | click to image 2.56 s (page load 1.60 s separately) | 1224×1584 JPEG, 192,570 B |
| pdf-to-png | in-browser pdf.js | 1 | click to image 2.12 s (page load 0.95 s separately) | 1224×1584 PNG, 255,420 B |
Three things to read from it:
- The Chromium engine is an order of magnitude slower than LibreOffice. For the same one-page document, markdown-to-pdf took over 11 seconds on all three runs and html-to-pdf 8 seconds, while the three LibreOffice directions ranged from 8 seconds down to 1.2.
time_starttransferandtime_totaldiffer by tens of milliseconds, so almost all of it is waiting for the first byte, not downloading. - LibreOffice has a visible cold start: word-to-pdf took 8.01 s the first time and 2.93 s a few minutes later; ppt-to-pdf, run right after docx and xlsx, took 1.22 s. Chromium showed no such warm-up, with all three Markdown runs between 11 and 15 seconds.
- Most of the browser-side 2 seconds is the first load of the pdf.js library. The file really did stay in the browser: zero upload requests intercepted on both runs.
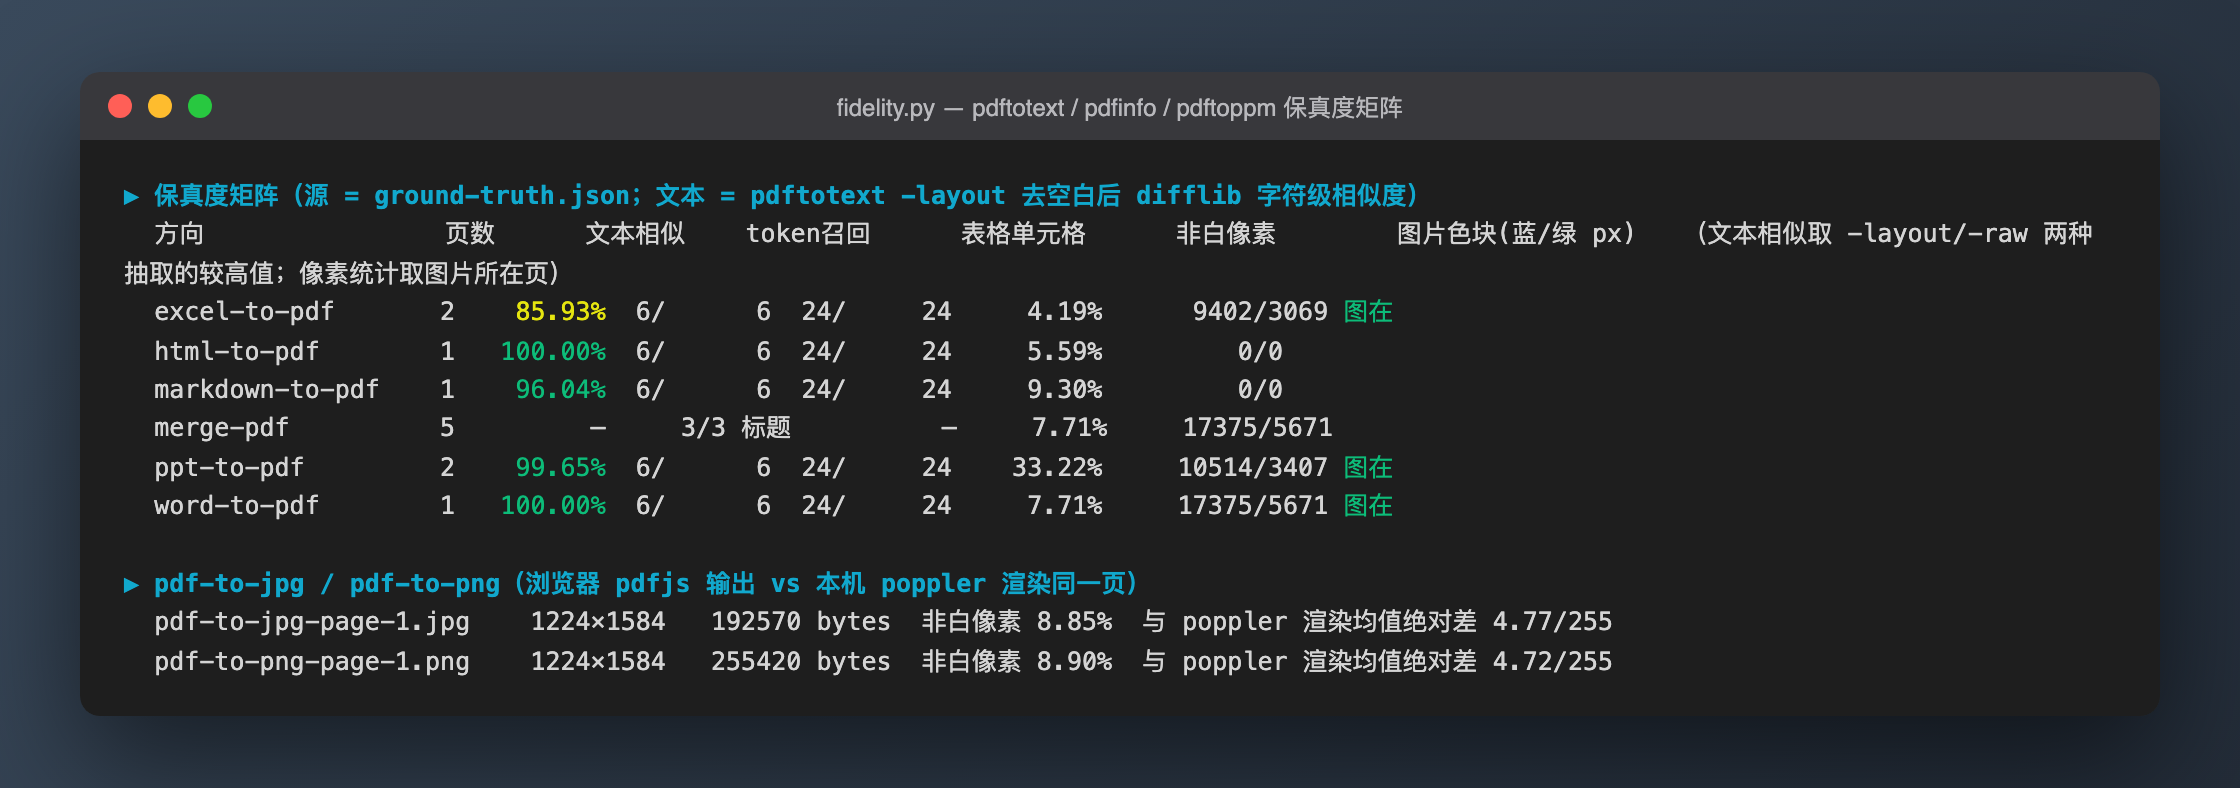
Fidelity matrix (text similarity is the higher of -layout and -raw extraction; pixel stats are taken from the page that holds the figure):
| Direction | Pages | Text similarity | Marker tokens | Table cells | Figure |
|---|---|---|---|---|---|
| word-to-pdf | 1 | 100.00% | 6/6 | 24/24 | present (blue 17,375 / green 5,671 px) |
| html-to-pdf | 1 | 100.00% | 6/6 | 24/24 | no figure in source |
| ppt-to-pdf | 2 | 99.65% | 6/6 | 24/24 | present (page 2, blue 10,514 / green 3,407) |
| markdown-to-pdf | 1 | 96.04% | 6/6 | 24/24 | no figure in source |
| excel-to-pdf | 2 | 85.93% | 6/6 | 24/24 | present (blue 9,402 / green 3,069) |
| merge-pdf | 5 = 1 + 2 + 2 | all 3 titles found | — | — | present |
| pdf-to-jpg | 1 image | mean abs diff vs poppler render of the same page 4.77 / 255 | — | — | — |
| pdf-to-png | 1 image | 4.72 / 255 | — | — | — |
The Word direction is a clean sheet: title, four paragraphs, marker line, bordered 6×4 table, figure and closing line all present and in place:
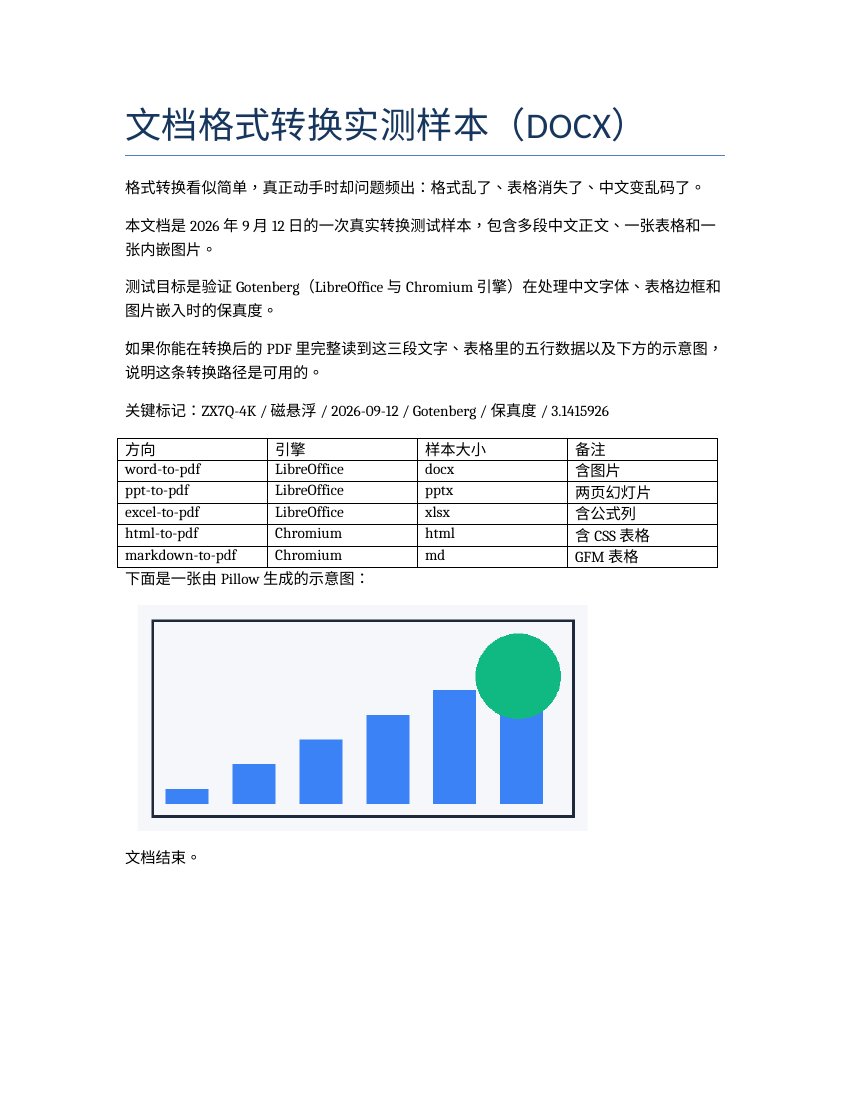
The three that did not score 100% each have a specific cause, not a vague "average quality":
- excel-to-pdf 85.93%: the sheet was split horizontally across two pages. I set column A to 60 characters and the next four to 16 each, wider than A4 portrait can print, so LibreOffice pushed the "sample / notes / value" columns and the total onto page 2 under its default page setup, and the long sentence in A5 was clipped at the page edge. All 24 cells and 6 markers survived and the
SUMformula evaluated to 1665; the reader just has to stitch two pages together. That is where the similarity score went. - ppt-to-pdf 99.65%: everything is there, but slide 2 overlaps. The title "表格与图片 ZX7Q-4K / 磁悬浮 / 2026-09-12" wrapped to two lines and sat on top of the table; cells like "word-to-pdf" wrapped and grew the rows, so the table extended down into the text box I had placed at 4.5 inches. The source slide was simply too dense and LibreOffice rendered it as-is. PowerPoint is not installed here, so I could not check how it would lay out the same file.
- markdown-to-pdf 96.04%: the code block is clipped on the right. The
curl ... -o out.pdfline is wider than the 800px body; the wrapper template givespreanoverflow-x: auto, which scrolls on screen but has no scrollbar in print, andpdftotextrecovers that line only up to/api/c. The four paragraphs, the table and the markers are intact.
Fonts are the other thing you only see by testing. pdffonts on three of the PDFs:
| Direction | Embedded fonts |
|---|---|
| markdown-to-pdf | NotoSansCJKjp-Regular |
| html-to-pdf | NotoSansCJKsc-Bold / Regular |
| word-to-pdf | NotoSansCJKhk-Regular + Carlito (Calibri substitute) + NotoSerif |
The Markdown wrapper asks for font-family: -apple-system, "Noto Sans SC", ...; no font by that name exists in the Gotenberg image, so fontconfig fell back to the Japanese variant of Noto Sans CJK. My hand-written HTML declares lang="zh" and "Noto Sans CJK SC" and got the Simplified Chinese variant. I could not spot a wrong glyph in this sample by eye, but the Japanese variant uses different default shapes for some Han characters, and a different batch of text could expose it. The DOCX case is LibreOffice's own substitution: Calibri becomes the metric-compatible Carlito, and the Chinese text lands on the Hong Kong variant.
Pitfalls
- macOS ships bash 3.2, which has no
declare -Aassociative arrays. I mapped directions to files with[word-to-pdf]=src/sample.docxand gotword: unbound variable: bash 3.2 evaluated the bracket contents as arithmetic. Acasefunction fixes it, or use/opt/homebrew/bin/bashexplicitly. The error happened before any curl call, so no quota was burned. pdftotext -layoutinterleaves table columns and produces false "missing cell" reports. On the slide with the table, "word-to-pdf" wrapped onto two lines, and in-layoutmode the two halves were separated by content from other columns on the same line, so the whitespace-stripped text never contained the original word. The first version of the script reported 19/24. Taking the union of-layoutand-rawextraction gives 24/24. Use content-stream order to judge whether text survived, and-layoutonly to judge layout.- "Figure possibly lost" was my own page-counting error. The first script only rendered page 1 for the color count; the slide with the picture is page 2, so it reported a lost image. Pixel statistics have to come from the page that holds the figure, otherwise you are measuring blank paper.
- Set "fit to one page wide" before converting Excel. If the column widths exceed the paper width, both LibreOffice and Excel split horizontally, and text clipped at the page edge is by design, not a broken conversion.
- A single over-long code line in Markdown gets clipped in the PDF; it does not wrap. That follows from the site's wrapper template using
pre { overflow-x: auto }in print media; the fix iswhite-space: pre-wraponpre. This and the font-name fallback above are problems in our own tool surfaced by this test, and both were fixed the same day: the template now declares<html lang="zh-CN">, asks for the font that actually exists in the image,"Noto Sans CJK SC", and setspretowhite-space: pre-wrap; word-break: break-all. Verification: the patched template was applied to the HTML rendered from the same Markdown file and pushed through the production html-to-pdf direction (the same Chromium).pdffontsnow lists only NotoSansCJKsc, and the curl line wraps onto two lines with-o out.pdffully present in thepdftotextoutput. - A bare curl gets a 403 unless it sends a browser User-Agent. The response headers show no Cloudflare trace (
server: nginx/1.26.2), so the block happens at the site's own layer.
Raw outputs, source files, the four scripts (make-sources.py / run-server.sh / run-pdfjs.mjs / fidelity.py) and results.jsonl are kept in the repository under tmp/2026-09-12-doc-convert/; every number in the tables traces back there.
FAQ
Why does conversion lose formatting even when using good tools?
Format conversion is fundamentally a lossy process when moving from a richer format to a simpler one. HTML supports hundreds of CSS properties; Markdown supports a handful of formatting options. A tool can only convert what the target format can express. When a source document uses a feature the target format doesn't support (merged table cells, sidebars, custom fonts), that feature is either dropped or approximated.
Can I batch convert multiple files automatically?
Yes. Pandoc supports batch conversion via shell scripting. For more complex workflows (DOCX files with images, PDFs requiring OCR), tools like make or simple Python scripts can orchestrate multi-step conversion pipelines across hundreds of files. For very large migrations (thousands of files), dedicated migration services may be more cost-effective.
When are paid converters worth it over free options?
Paid converters and services are worth considering for: high-volume migrations where manual cleanup time has real cost, scanned PDFs where OCR accuracy matters, documents with complex layouts that free tools handle poorly, and production workflows where consistent output quality is required. For occasional personal use, the free tools in this guide handle the vast majority of cases well.
Conclusion
Format conversion is a solved problem for common paths — Markdown → HTML, DOCX → Markdown, HTML → Markdown — with mature tools like Pandoc handling most cases reliably. The difficulty increases when converting from locked formats (PDF, especially scanned) or when source documents rely on formatting features the target format can't express.
The practical rule: for anything important, always preview the converted output before using it, and budget time for cleanup on complex documents. For routine conversions, automate with Pandoc or a dedicated tool and spend your time on the 10–15% that needs human judgment.