Claude Code Hooks: Custom Automation Workflows
This article originally covered only the concepts. On 2026-09-19 I added the "Hands-On Lab" section at the end: a fully isolated hook laboratory on Claude Code 2.1.270, with all 8 events wired to the same capture script, every stdin JSON dumped to disk, and a hook-marker-file plus tool-marker-file pair to confirm independently whether the tool actually ran. The headline: three things in the body below are wrong — only exit 2 blocks a tool (exit 1 and exit 3 both let it through), the singular "hook": {…} config key is silently ignored, and neither $CLAUDE_FILE_PATH nor $CLAUDE_TOOL_INPUT exists in 2.1.270. The original text is left untouched; the lab section below gives the real readings and the corrected patterns.
What Are Hooks
Hooks are Claude Code's automation extension mechanism. They let you run custom scripts automatically when specific events occur — before or after Claude calls a tool. Use hooks to auto-format code, block dangerous commands, or send notifications.
Hooks execute deterministically on your local machine without consuming LLM tokens, making them ideal for building reliable automation workflows.
Hook Event Types
| Event | When It Fires |
|---|---|
PreToolUse |
Before a tool call executes |
PostToolUse |
After a tool call completes |
Notification |
When Claude sends a notification |
Stop |
When Claude finishes a response |
Configuration
Configure hooks in .claude/settings.json:
{
  "hooks": {
    "PreToolUse": [
      {
        "matcher": "Edit|Write",
        "hook": {
          "type": "command",
          "command": "echo 'File is about to be modified'"
        }
      }
    ],
    "PostToolUse": [
      {
        "matcher": "Edit|Write",
        "hook": {
          "type": "command",
          "command": "npx prettier --write $CLAUDE_FILE_PATH"
        }
      }
    ]
  }
}
The matcher field supports regex to match tool names like Edit, Write, or Bash.
Practical Examples
Auto-Lint After File Save
{
  "PostToolUse": [
    {
      "matcher": "Edit|Write",
      "hook": {
        "type": "command",
        "command": "npx eslint --fix $CLAUDE_FILE_PATH 2>/dev/null || true"
      }
    }
  ]
}
Block Dangerous Commands
{
  "PreToolUse": [
    {
      "matcher": "Bash",
      "hook": {
        "type": "command",
        "command": "if echo \"$CLAUDE_TOOL_INPUT\" | grep -qE 'rm\\s+-rf\\s+/|DROP\\s+DATABASE'; then echo 'BLOCKED: Dangerous command detected' >&2; exit 1; fi"
      }
    }
  ]
}
When a hook script exits with a non-zero status, the corresponding tool call is blocked.
Send Notification on Completion
{
  "Stop": [
    {
      "matcher": "",
      "hook": {
        "type": "command",
        "command": "osascript -e 'display notification \"Claude finished the task\" with title \"Claude Code\"'"
      }
    }
  ]
}
Best Practices
- Keep scripts fast: Hooks block Claude's execution, so avoid long-running tasks
- Handle errors gracefully: Use
|| trueto prevent non-critical failures from blocking the workflow - Leverage environment variables: Claude injects
$CLAUDE_FILE_PATH,$CLAUDE_TOOL_INPUT, and other context variables - Share with your team: Put hooks in the project-level
.claude/settings.jsonand commit to the repository
FAQ
What is the difference between Hooks and MCP?
Hooks are deterministic local scripts that trigger on specific events, ideal for automated checks and formatting. MCP is a protocol that lets Claude access external tools and data sources on demand. They are complementary — hooks for automation rules, MCP for extended capabilities.
What happens if a hook script fails?
If a PreToolUse hook exits with a non-zero status, the tool call is blocked. If a PostToolUse hook fails, Claude receives the error but continues with subsequent operations.
What environment variables are available in hooks?
Claude Code automatically injects context variables including CLAUDE_FILE_PATH (the file being operated on) and CLAUDE_TOOL_INPUT (the tool's input parameters). Available variables depend on the event type and tool being used.
Hands-On Lab: All 8 Events, Exit Codes, Matchers and Latency on 2.1.270
The problem
The body above follows the official docs. Plenty of people get it working; plenty of people don't — and "it doesn't work" is unusually hard to debug with hooks: a malformed config doesn't error, a hook that never fires doesn't error, a wrong exit code doesn't error. All you see is "it seems to do nothing."
I fell into one of those traps before; that write-up lives separately in The stdin trap in Claude Code hooks (that one is about how a hook script reads its own stdin — no overlap with this piece). This time I wanted to measure the whole external contract: which events actually fire, what JSON the hook really receives, what each exit code means, how to write a matcher that hits, and what a hook costs in latency.
Analysis
Turning those questions into real readings runs into three obstacles:
- "The hook never fired" and "the hook fired but didn't do anything" look identical in logs. A hook's own log can't tell you whether
PreToolUseskipped or ran-and-failed-to-block. - This machine already runs two production hooks (a global
~/.claude/hooks/log_tool_io.pyand the repo's.claude/hooks/lessons-inbox-capture.sh). The experiment must not touch or pollute either. - Every cold
claude -pburns ~50K cache-creation tokens — about $0.32 a session on Opus. Dozens of runs gets expensive fast.
Approach and trade-offs
Final design: a dedicated CLAUDE_CONFIG_DIR + --settings <absolute path> + one work directory per run + a Haiku driver + double marker files.
- Isolate with
--settings, not.claude/settings.json:--settingstakes an arbitrary path, so the lab config never lands in a scanned directory;CLAUDE_CONFIG_DIRpoints at an emptytmp/directory so user-level hooks can't leak in either. (Rejected: editing the repo's real.claude/settings.json— pollutes production hooks and needs a manual revert every time.) - Double marker files are the key idea: the hook appends a line to
hook-ran.txton every fire, and the Bash command the model runs writestool-ran.txt. Cross the two and "how many times the hook fired" and "whether the tool actually executed" become two independent facts, no guessing. (Rejected: trusting the model's prose — it will happily claim "I ran it.") - Haiku 4.5 as the driver: 38 sessions for $1.5248, about $0.04 each. (Rejected: hitting
/v1/messagesdirectly to synthesize hook scenarios — the local Anthropic proxy only admits Claude Code clients and 503s any script, so that road is closed.) --output-format jsonfor time and cost:duration_ms,num_turnsandtotal_cost_usdcome from the CLI itself, no stopwatch. End-to-endwall_sis recorded separately in the shell and read alongside.
Every run has the same shape:
claude -p "<minimal task>" \
  --settings /abs/path/to/lab/xxx.settings.json \
  --output-format json \
  < /dev/null          # without this it waits 3s for stdin — ruins the latency numbers
Experiment 1: which of the 8 events actually fire
A minimal task (Read a file → Write a file → echo lab-probe), with all 8 events wired to the same capture.sh that appends the raw stdin JSON to events.jsonl:
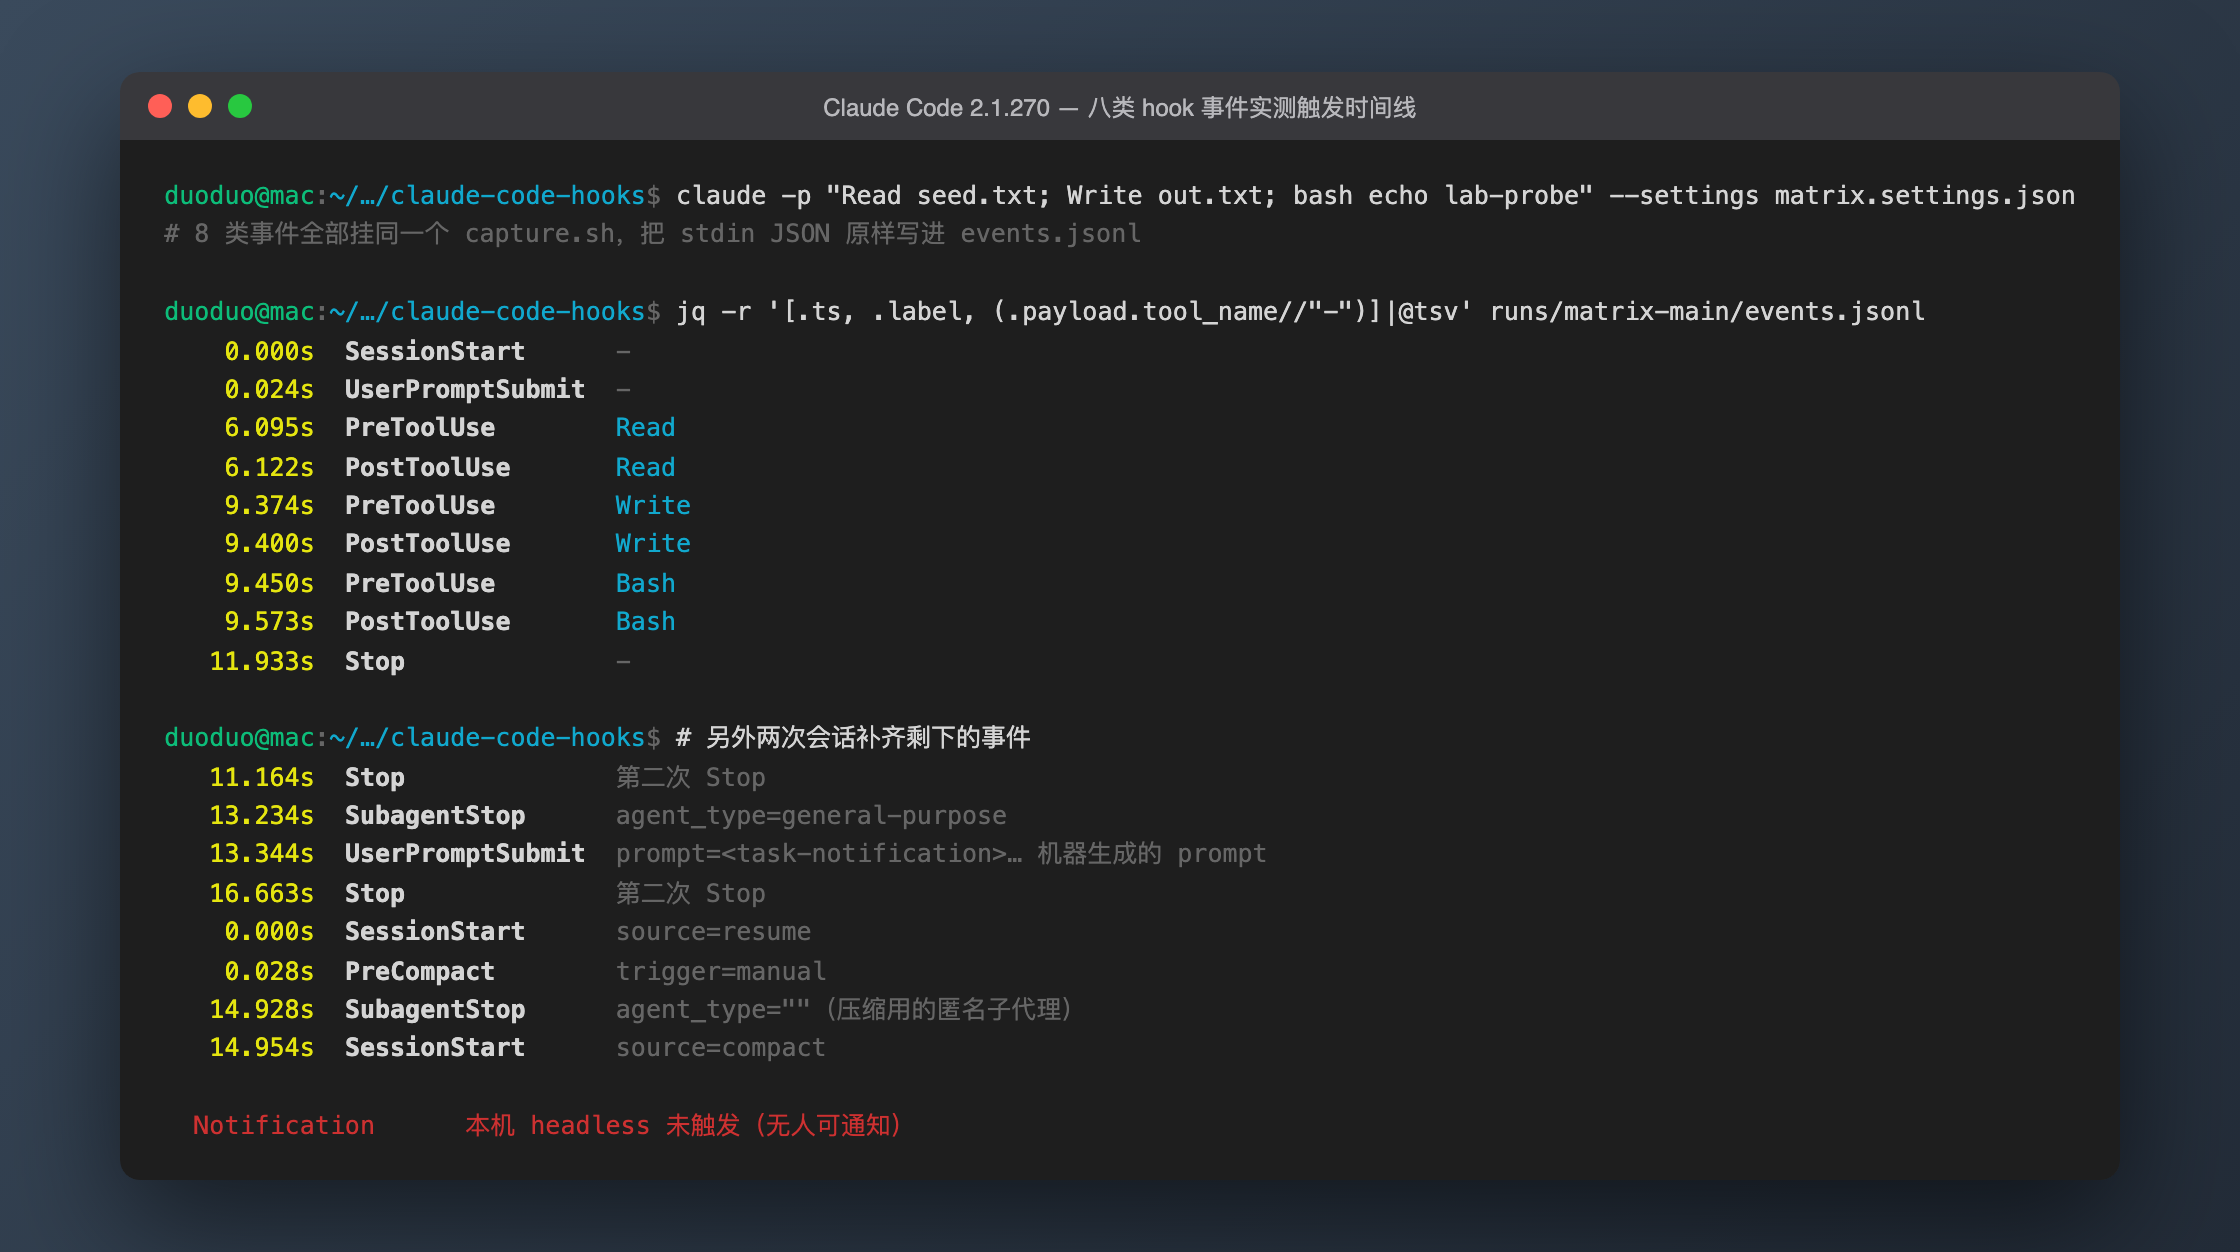
The main session fires 9 times, in this order (timestamps relative to the first fire):
| Time | Event | tool_name |
|---|---|---|
| 0.000s | SessionStart |
— |
| 0.024s | UserPromptSubmit |
— |
| 6.095s | PreToolUse |
Read |
| 6.122s | PostToolUse |
Read |
| 9.374s | PreToolUse |
Write |
| 9.400s | PostToolUse |
Write |
| 9.450s | PreToolUse |
Bash |
| 9.573s | PostToolUse |
Bash |
| 11.933s | Stop |
— |
Note the PreToolUse → PostToolUse gaps: 26–123ms, which is the tool's real execution time. The gap between tool calls is 3.2 seconds — that's the model thinking. Hook overhead has to be compared against "model thinking," not against "tool execution" — the latency experiment below confirms this.
The remaining three events need separate sessions. Asking the model to spawn a background subagent:
| Time | Event | Note |
|---|---|---|
| 8.992s | PreToolUse |
tool_name is Agent, not the Task you often see in docs |
| 11.164s | Stop |
the main session finished first |
| 13.234s | SubagentStop |
agent_type=general-purpose |
| 13.344s | UserPromptSubmit |
prompt body is <task-notification>… — machine-generated prompts go through this event too |
| 16.663s | Stop |
second Stop |
Neither of those is in the docs. If you want a matcher for subagent calls, write Agent. If you do "user input screening" in UserPromptSubmit, be ready to receive prompts no human typed — otherwise your own rule blocks every returning background task.
Then --resume a session and run /compact manually:
| Time | Event | Note |
|---|---|---|
| 0.000s | SessionStart |
source=resume |
| 0.028s | PreCompact |
trigger=manual |
| 14.928s | SubagentStop |
agent_type="" — compaction runs as an anonymous subagent |
| 14.954s | SessionStart |
source=compact |
Compaction emits an extra SubagentStop and an extra SessionStart. If your SessionStart hook does heavy work (injecting project context, say), it runs many times in a long session, not once.
Notification did not fire on this machine. Two attempts came back empty: one asking the model to run a command needing approval (5 events, no Notification), one letting it idle (3 events, no Notification). The reason is plain — claude -p is headless; there is nobody to notify, which is exactly what the CLAUDE_CODE_SESSION_ATTENDED environment variable is about. The following is a guess, not verified: Notification most likely fires only in an interactive TTY session, when waiting for permission or idling; testing it probably requires a real terminal session driven by hand. I could not reproduce it headless, so I'm not inventing numbers.
Experiment 2: the stdin fields a hook really receives
This table is read out of the dumped events.jsonl, not copied from docs. Every event carries session_id, transcript_path, cwd and hook_event_name; the differences:
| Event | Event-specific fields (measured on 2.1.270) |
|---|---|
SessionStart |
source (startup / resume / compact) |
UserPromptSubmit |
prompt_id, permission_mode, prompt |
PreToolUse |
prompt_id, permission_mode, tool_name, tool_input, tool_use_id |
PostToolUse |
the same plus tool_response (for Read: {type, file:{filePath, content, numLines, totalLines}}) |
Stop |
stop_hook_active, last_assistant_message, background_tasks, session_crons |
SubagentStop |
agent_id, agent_type, agent_transcript_path, stop_hook_active, last_assistant_message |
PreCompact |
trigger (manual / auto), custom_instructions |
Notification |
did not fire here — no measured fields |
The environment-variable claim in the body above is wrong. The CLAUDE* variables actually present in the hook process are:
CLAUDECODE, CLAUDE_BASH_MAINTAIN_PROJECT_WORKING_DIR, CLAUDE_CODE_ATTRIBUTION_HEADER,
CLAUDE_CODE_CHILD_SESSION, CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC, CLAUDE_CODE_ENTRYPOINT,
CLAUDE_CODE_EXECPATH, CLAUDE_CODE_MAX_OUTPUT_TOKENS, CLAUDE_CODE_MESSAGING_SOCKET,
CLAUDE_CODE_MESSAGING_TOKEN, CLAUDE_CODE_SESSION_ATTENDED, CLAUDE_CODE_SESSION_ID,
CLAUDE_CODE_USE_VERTEX, CLAUDE_CONFIG_DIR, CLAUDE_EFFORT, CLAUDE_PID, CLAUDE_PROJECT_DIR
CLAUDE_FILE_PATH and CLAUDE_TOOL_INPUT are both UNSET. Take the path out of the stdin JSON instead:
# ❌ the pattern in the body: both variables are empty on 2.1.270,
#    so prettier formats an empty path
npx prettier --write $CLAUDE_FILE_PATH

# ✅ measured working: read tool_input.file_path from stdin JSON
payload=$(cat)
f=$(printf '%s' "$payload" | jq -r '.tool_input.file_path // empty')
[ -n "$f" ] && npx prettier --write "$f"
Also: CLAUDE_PROJECT_DIR measures as the cwd where claude was launched, not the git root. Start a session in a subdirectory and any script path built from it points at the wrong place.
Experiment 3: what exit codes actually mean
This is the worst error in the body above, which says "when a hook script exits with a non-zero status, the corresponding tool call is blocked." Measured: it isn't.
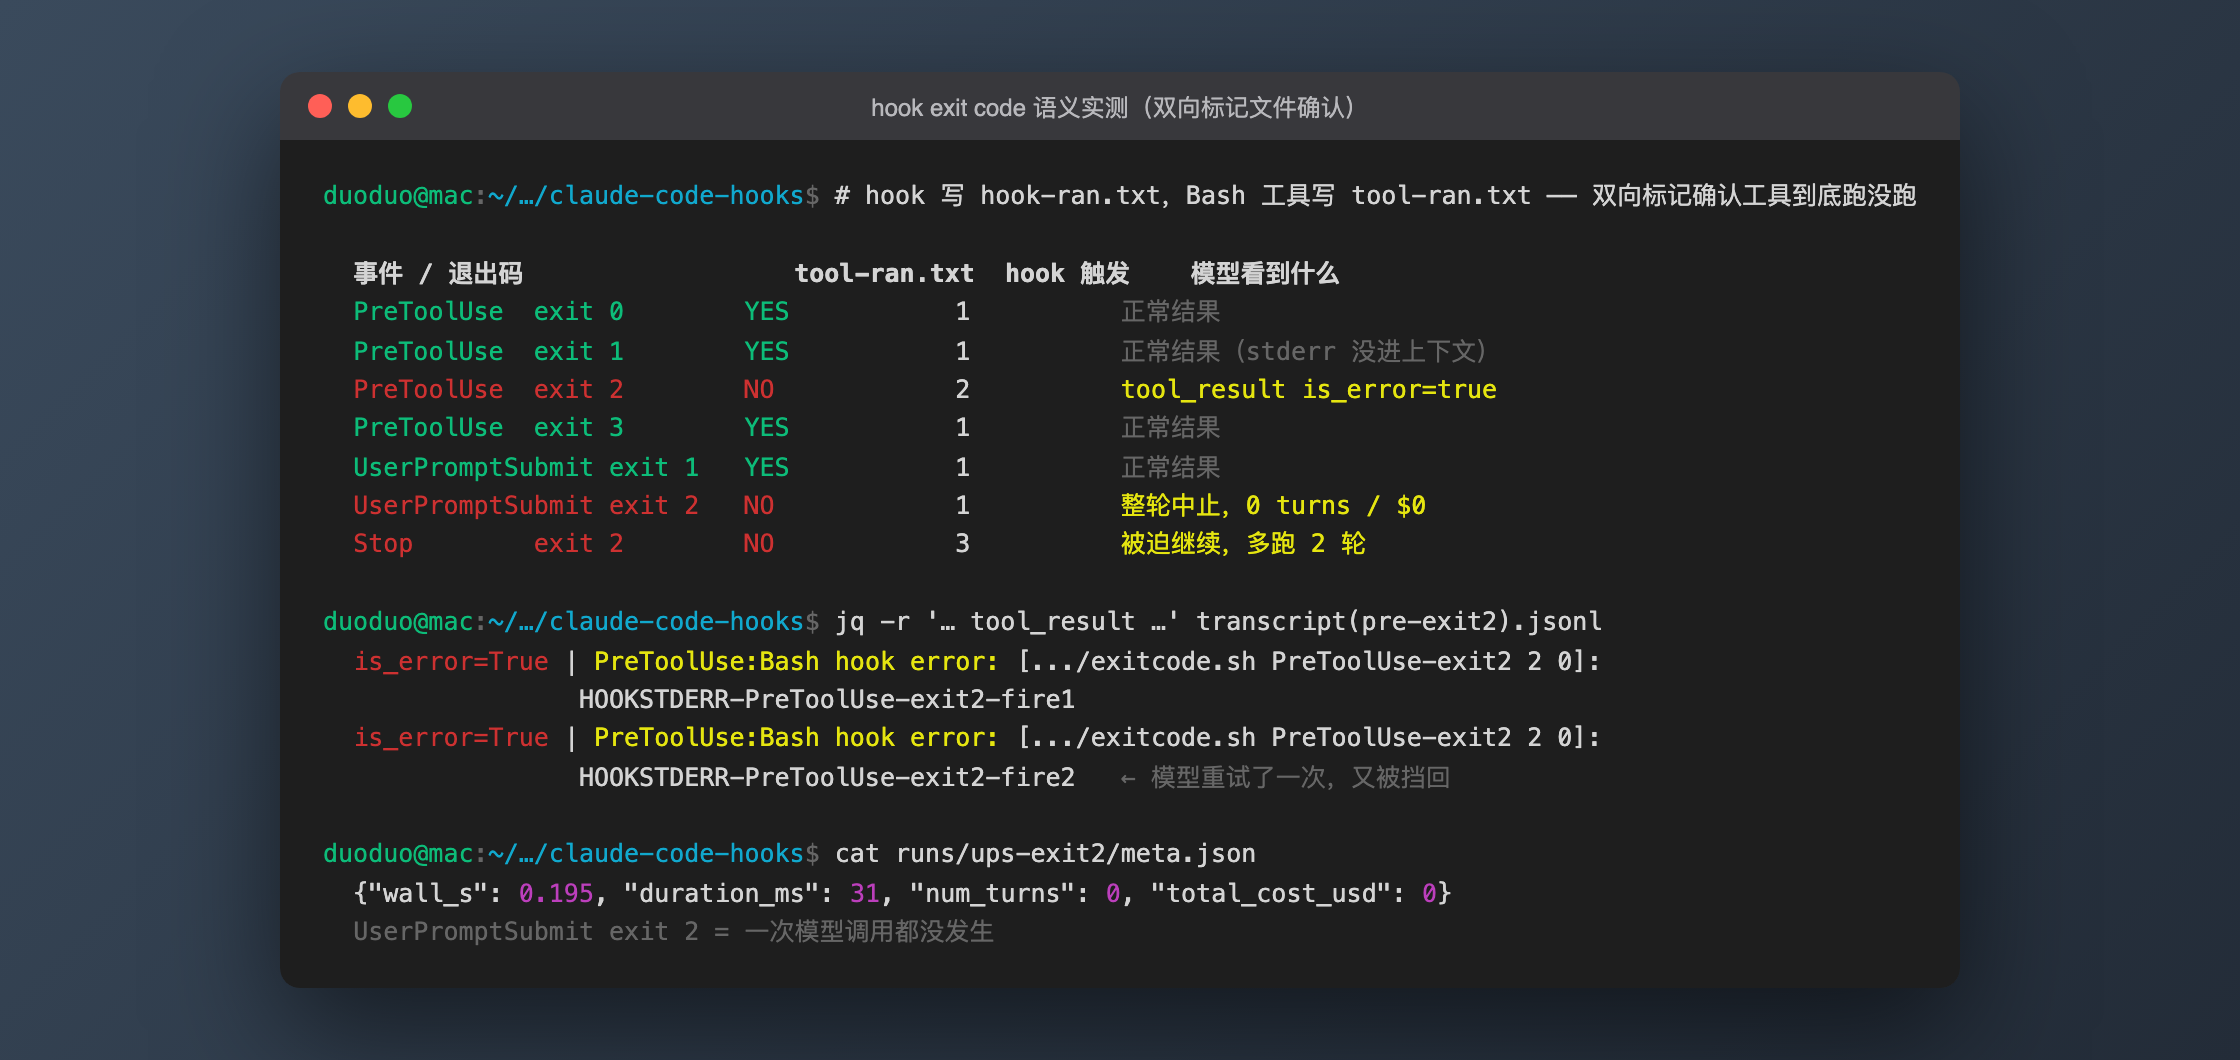
One isolated session per exit code; the hook writes hook-ran.txt, the Bash tool writes tool-ran.txt:
| Config | tool-ran.txt |
hook fires | turns | cost | what the model saw |
|---|---|---|---|---|---|
PreToolUse exit 0 |
YES | 1 | 2 | $0.0695 | normal result |
PreToolUse exit 1 |
YES | 1 | 2 | $0.0405 | normal result; stderr never reached the context |
PreToolUse exit 2 |
NO | 2 | 3 | $0.0496 | tool_result with is_error=true |
PreToolUse exit 3 |
YES | 1 | 2 | $0.0409 | normal result |
UserPromptSubmit exit 1 |
YES | 1 | 2 | $0.0409 | normal result |
UserPromptSubmit exit 2 |
NO | 1 | 0 | $0 | whole turn aborted; the model was never called |
Stop exit 2 |
— | 3 | 3 | $0.0797 | forced to continue for 2 extra turns |
Only exit 2 has blocking semantics. On PreToolUse, exit 1 and exit 3 are exactly equivalent to allowing the call, and the hook's stderr doesn't even reach the model's context — you think you blocked a dangerous command; it ran.
The marker files aren't the only evidence. The session transcript holds two real tool_result entries:
is_error=True | PreToolUse:Bash hook error: [.../exitcode.sh PreToolUse-exit2 2 0]:
               HOOKSTDERR-PreToolUse-exit2-fire1
is_error=True | PreToolUse:Bash hook error: [.../exitcode.sh PreToolUse-exit2 2 0]:
               HOOKSTDERR-PreToolUse-exit2-fire2     ← the model retried and got blocked again
Two details: the hook's stderr goes into the model's context verbatim (so write the rejection reason for the model to read), and a blocked model retries, which is why the hook fired twice instead of once — make your hook idempotent, don't bill or notify from the blocking branch.
The UserPromptSubmit exit 2 row has the best numbers: {"wall_s": 0.195, "duration_ms": 31, "num_turns": 0, "total_cost_usd": 0}. It aborts before the model is ever called: 31 milliseconds, zero cost. Input-side compliance checks (rejecting prompts containing secrets, say) belong here, not in PreToolUse.
Stop exit 2 drags the model back to work. My script carried a max-fires=2 safety valve — the third fire returns 0, which is the only reason it stopped. Without the valve it's an infinite loop. The stop_hook_active field in the stdin JSON exists for exactly this: it flips to true on re-entry. Use it instead of my counter file.
Experiment 4: ten matcher spellings, which ones hit
Ten matchers mounted side by side under a single PreToolUse; one session calling Read, Write and Bash once each:
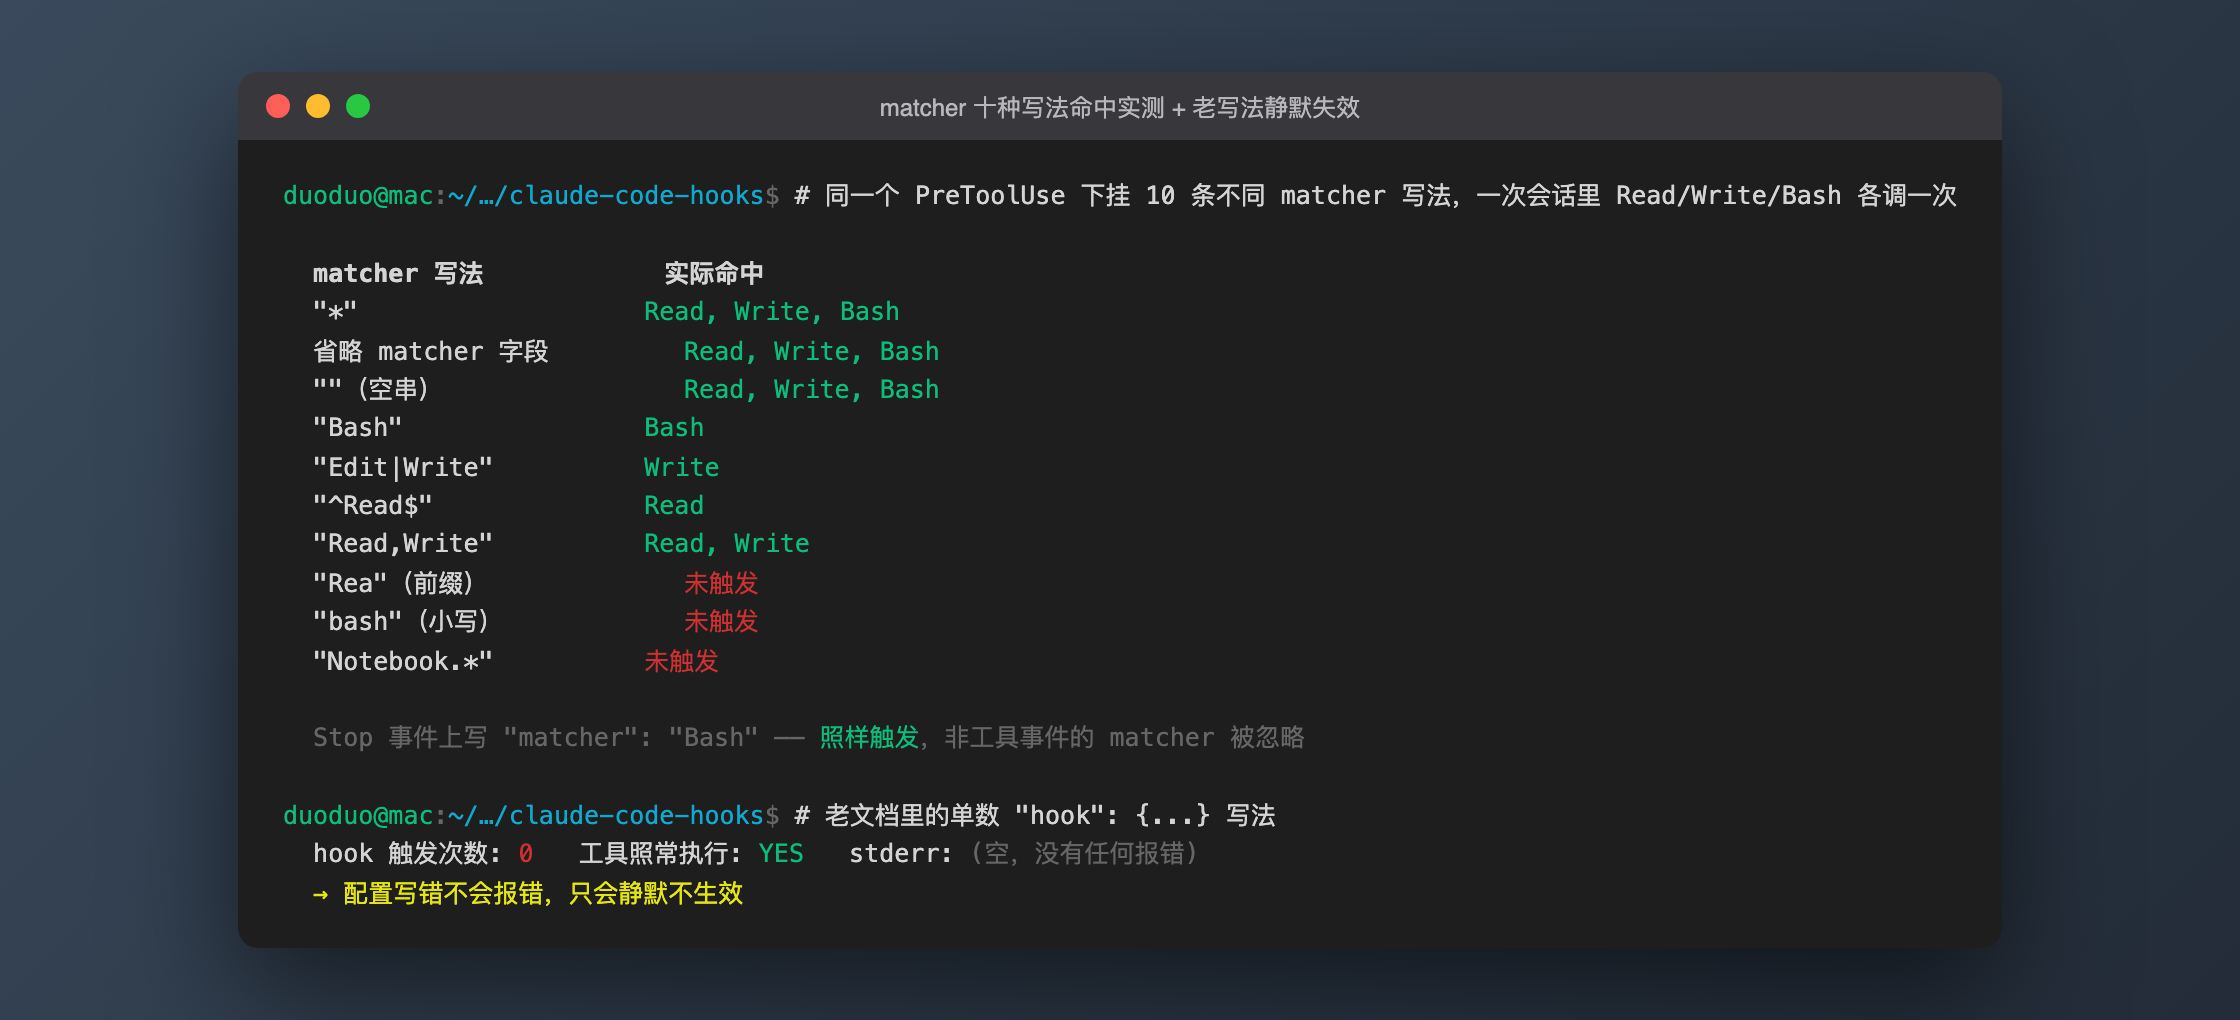
| Matcher | Actually hit |
|---|---|
"*" |
Read, Write, Bash |
matcher field omitted |
Read, Write, Bash |
"" (empty string) |
Read, Write, Bash |
"Bash" |
Bash |
"Edit|Write" |
Write |
"^Read$" |
Read |
"Read,Write" |
Read, Write |
"Rea" (prefix) |
no fire |
"bash" (lowercase) |
no fire |
"Notebook.*" |
no fire (no Notebook tool in this session) |
Three conclusions:
"*",""and omitting the field are equivalent in practice — all match everything.- Matching is whole-name, not substring —
"Rea"does not matchRead, which means the anchors in"^Read$"are redundant. Regex really does work (|fires), but don't expect substrings. - It is case-sensitive:
"bash"does not matchBash.
Also, putting "matcher": "Bash" on the Stop event — it fires anyway. Matchers on non-tool events are ignored outright: no effect, no error, no filtering.
Finally, the config format. The body above (and many tutorials) uses the singular "hook": {…}:
hook fires: 0 tool executed: YES stderr: (empty, no error at all)
2.1.270 only accepts the plural array "hooks": [{…}]. The singular form neither errors nor works — the hardest kind of failure, as noted at the top. The correct shape:
{
  "hooks": {
    "PreToolUse": [
      {
        "matcher": "Bash",
        "hooks": [
          { "type": "command", "command": "/abs/path/check.sh", "timeout": 5 }
        ]
      }
    ]
  }
}
Experiment 5: what a hook costs in latency
Same task (Read + Write + Bash — 9 hook fires per session) × 3 configurations × 3 runs, medians:
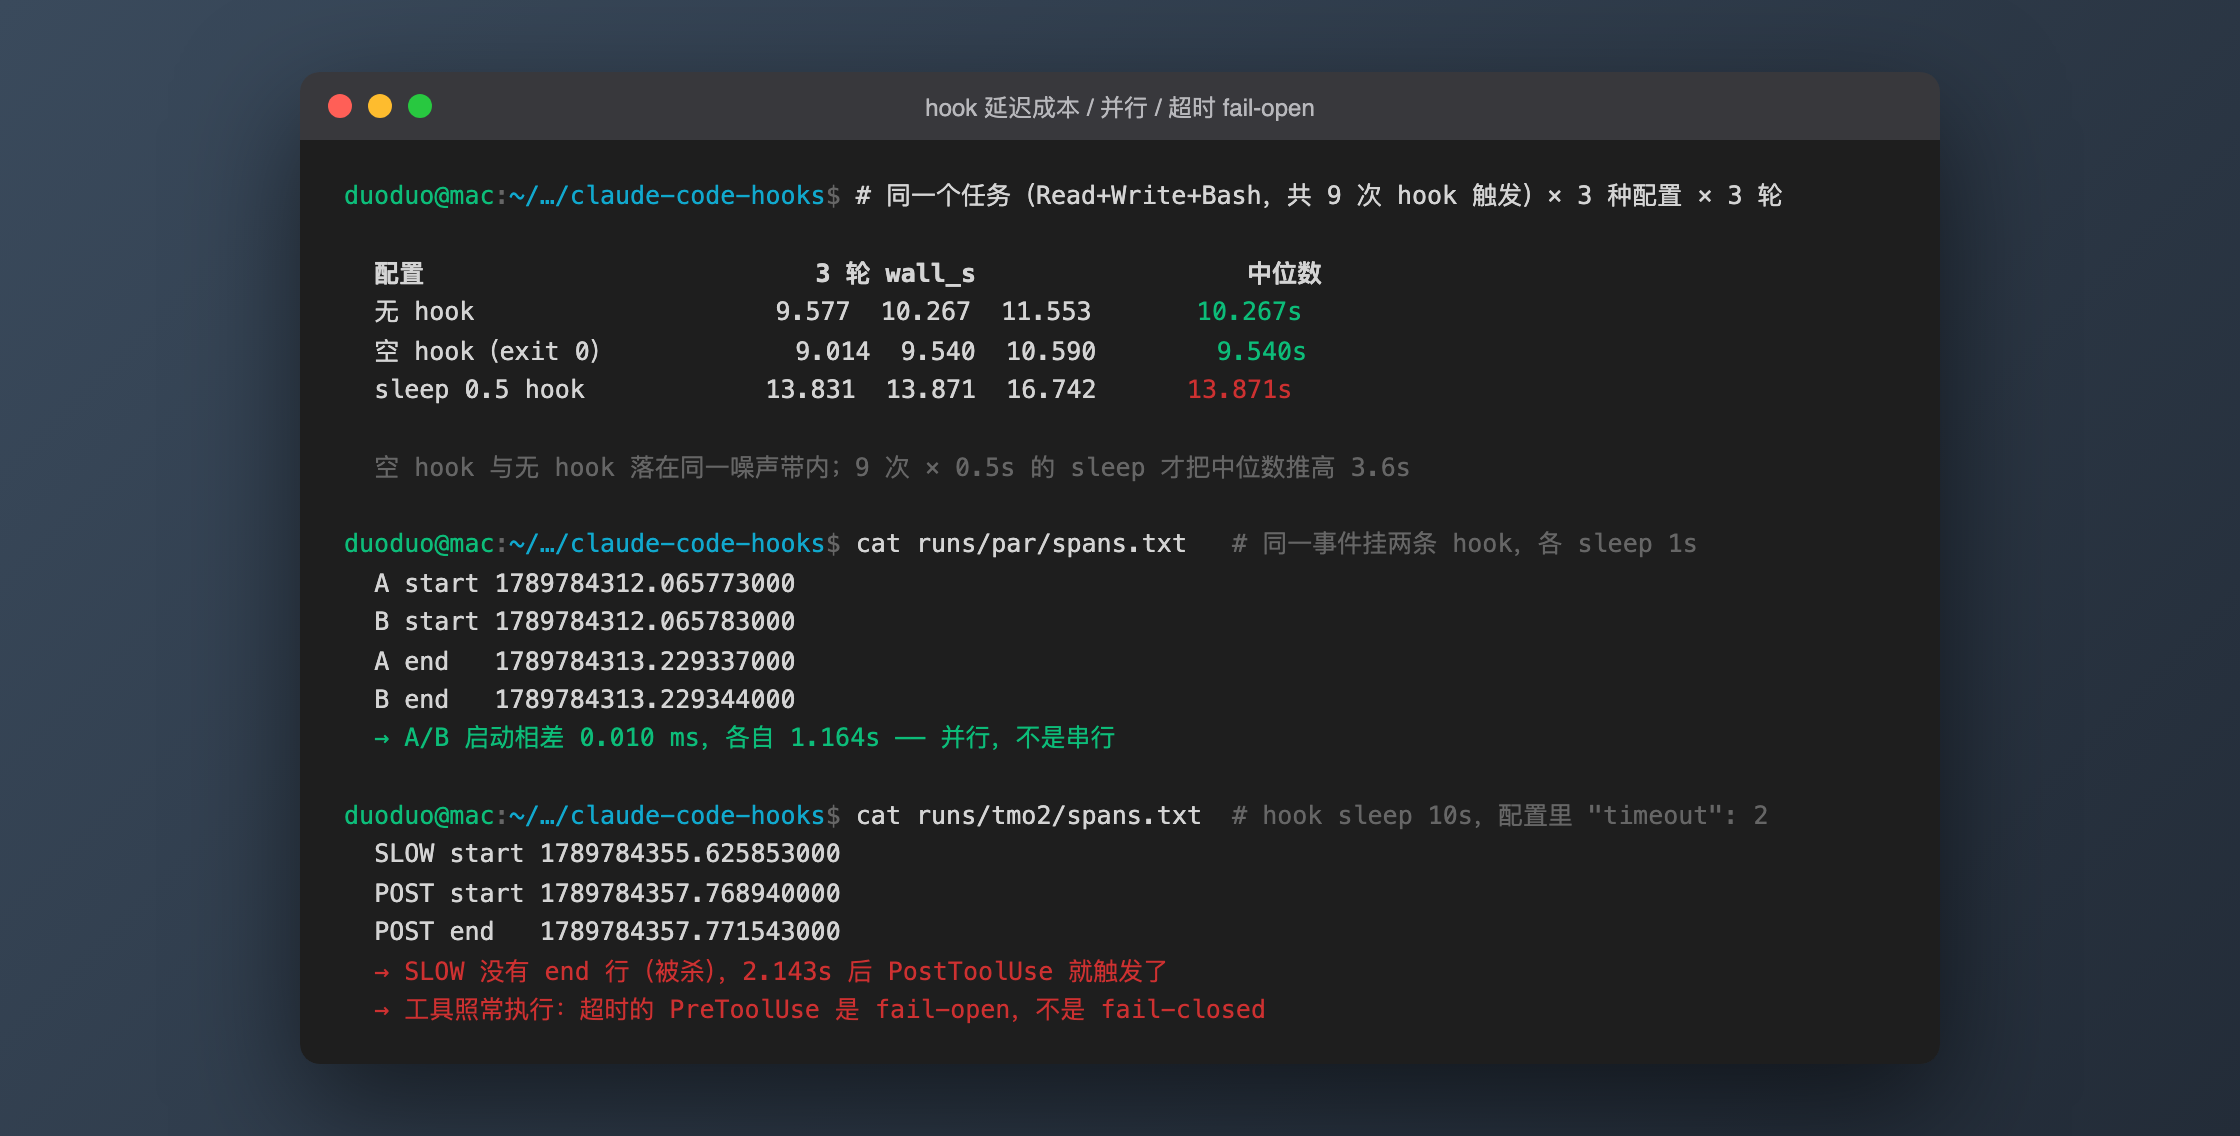
| Configuration | 3 runs, wall_s |
Median | API duration_ms median |
|---|---|---|---|
| no hook | 9.577 / 10.267 / 11.553 | 10.267s | 10.093s |
empty hook (exit 0) |
9.014 / 9.540 / 10.590 | 9.540s | 9.355s |
sleep 0.5 hook |
13.831 / 13.871 / 16.742 | 13.871s | 13.007s |
The empty-hook median is 0.7s lower than no hook at all — which doesn't mean hooks make things faster; it means the cost of 9 empty hooks is entirely inside the noise band of model response time. The spread across 3 runs is already 2 seconds. The only measurable effect is the sleep 0.5 group: 9 × 0.5s = 4.5s of theoretical overhead pushed the median up by 3.6s.
So: don't fear adding hooks, fear doing slow work inside them. A jq check or a grep is nothing next to a 3-second thinking pause; an npx eslint cold start (1–2s measured) multiplied by every Edit is very much something.
Two hooks on the same event run in parallel:
A start 1789784312.065773000
B start 1789784312.065783000
A end   1789784313.229337000
B end   1789784313.229344000
A and B start 0.010 milliseconds apart and each take 1.164s — two hooks that each sleep 1 cost 1.164s total, not 2s.
Timeout behaviour is fail-open. With "timeout": 2 and a sleep 10 in the hook:
SLOW start 1789784541.…       ← start only, no end line: the process was killed
POST start 1789784543.…       ← PostToolUse fired 2.143s later
tool-ran.txt exists — a timed-out PreToolUse does not block; the tool runs. If your security check is a script that can get slow (fetching a policy over the network, say), the day it gets slow is the day it stops protecting you.
Results
The one-line version, ready to paste into your config:
- The config key is
"hooks": [...](plural array); singular"hook": {...}fails silently. - To block, the exit code must be 2;
1and3both allow, and stderr never reaches the model. - stderr is written for the model — phrase it as an actionable instruction ("use X instead of Y"), not
BLOCKED. - A model blocked by
exit 2retries, so hooks must be idempotent. - Get the file path via
jq -r '.tool_input.file_path', not$CLAUDE_FILE_PATH(doesn't exist). - Put input-side checks on
UserPromptSubmit: exit 2 aborts in 31ms with 0 turns and $0 — an order of magnitude cheaper than blocking atPreToolUse. - When a
Stophook forces continuation with exit 2, readstop_hook_activeor you get an infinite loop. - Matchers are case-sensitive and whole-name;
"*",""and omission are equivalent; matchers on non-tool events are ignored. - The subagent tool is named
Agent;UserPromptSubmitalso receives machine-generated<task-notification>prompts. - Don't fear adding hooks (empty ones are unmeasurable), fear slow work inside them; timeouts are fail-open, so don't build a security check that can get slow.
All readings come from 38 claude -p sessions costing $1.5248 in total; the raw JSONL and settings files are kept locally.
Pitfalls
Pitfall 1: "hook" vs "hooks" — one letter, silent failure.
Symptom: a config copied from an older tutorial does nothing; 0 hook fires, tool runs normally, stderr empty. Root cause: the 2.1.270 schema is {"matcher": ..., "hooks": [ ... ]}; the singular "hook" is an unknown key, ignored without validation. Fix: use the plural array — and when debugging any "hook doesn't work" problem, first mount a log-only exit 0 hook to prove the trigger path works at all, then debug your logic.
Pitfall 2: --settings only accepts absolute paths.
Symptom: --settings lab/matrix.settings.json reports Error: Settings file not found even though the file is right there. Root cause: relative paths resolve against the session's working directory, and every run of mine used its own work directory. Fix: always use absolute paths for --settings and for hook command entries.
Pitfall 3: headless runs waste 3 seconds waiting for stdin.
Symptom: claude -p prints Warning: no stdin data received in 3s before doing anything. For a latency experiment those 3 seconds destroy every reading. Fix: claude -p "..." < /dev/null. This applies to any scripted invocation, not just experiments.
Pitfall 4: a PostToolUse hook that modifies the file triggers a system reminder.
An accidental finding. Have a PostToolUse hook append to the file right after the model writes it (simulating a formatter) and the transcript grows a hook_additional_context attachment:
PostToolUse hook modified …/note.txt after your edit (likely a formatter). Your next Edit will not fail with a stale-file error, but if its
old_stringtargets a region the hook reformatted,Readthe file first.
So Claude Code knows formatter-style hooks exist and warns the model proactively. The good news: auto-formatting won't break the model's subsequent edits. The price: every such hook injects another paragraph into the context.