Articles
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
Industry news, technical articles, and product introductions
📚 Claude Tutorials Hub
40+ step-by-step Claude guides — prompt engineering, Claude Code, API, agents. Browse by topic →
Loading...
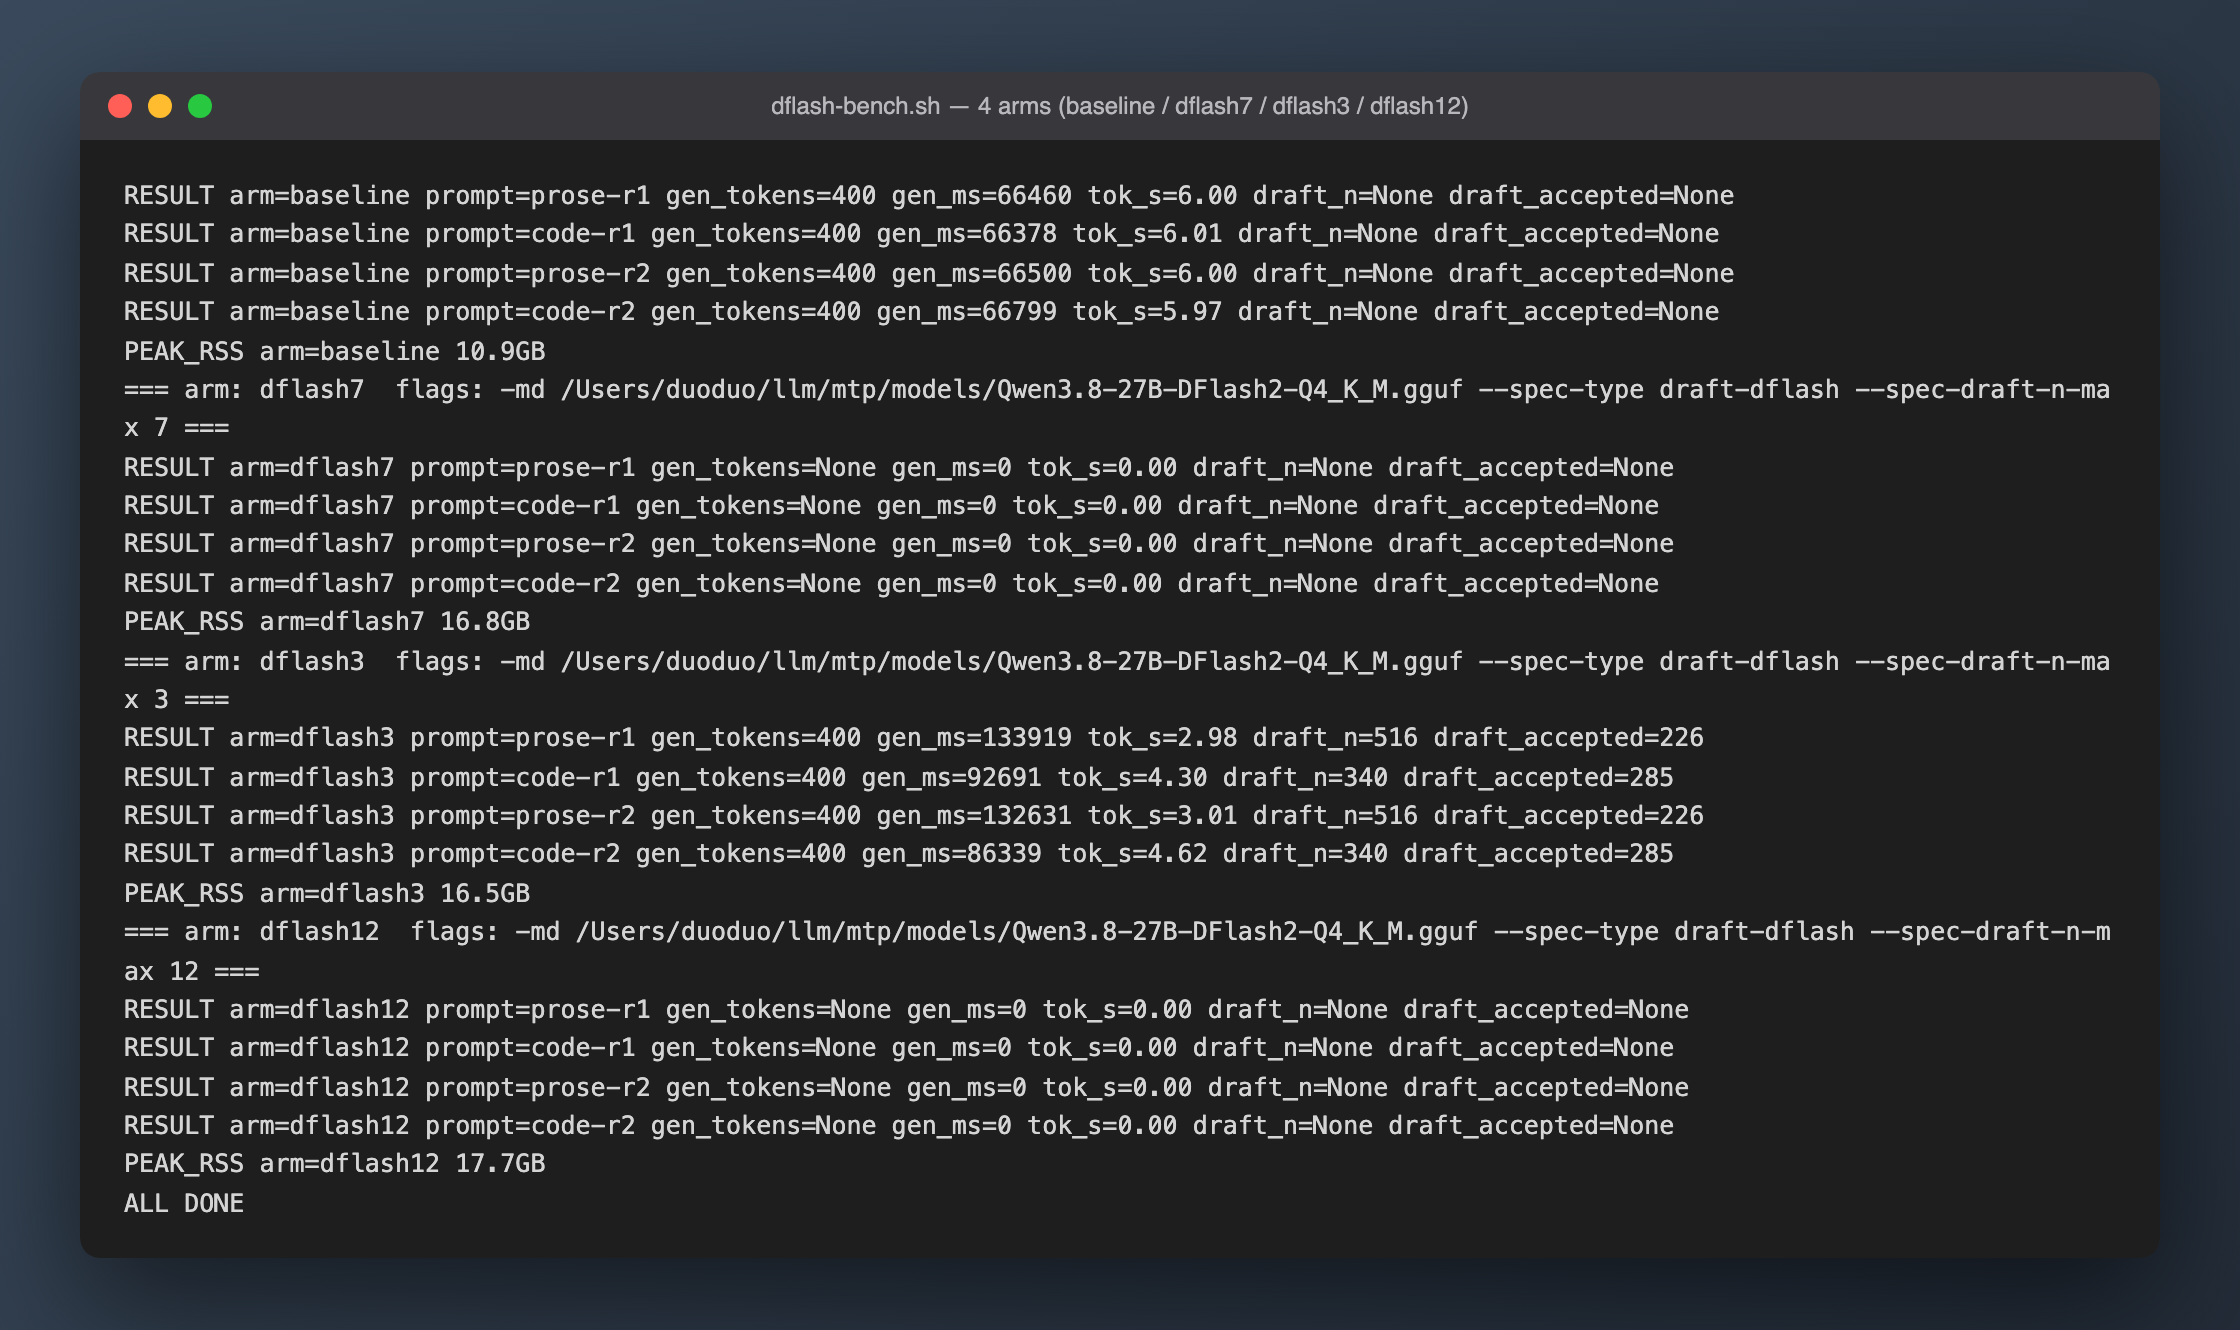
Part three of my speculative-decoding trilogy on a base Mac mini M4. llama.cpp merged DFlash 2 support with official GGUF drafts — and every configuration is a net slowdown. The README-recommended n-max 7 hits a reproducible Metal OOM on 24GB; the only stable setting cuts prose from 6.0 to 3.0 tok/s, and an 83.8% acceptance rate on code still loses 23%. Same algorithm, same machine, MLX gets 1.8–1.9x. The arithmetic shows why: 0.77s per speculative step loses even at 100% acceptance.
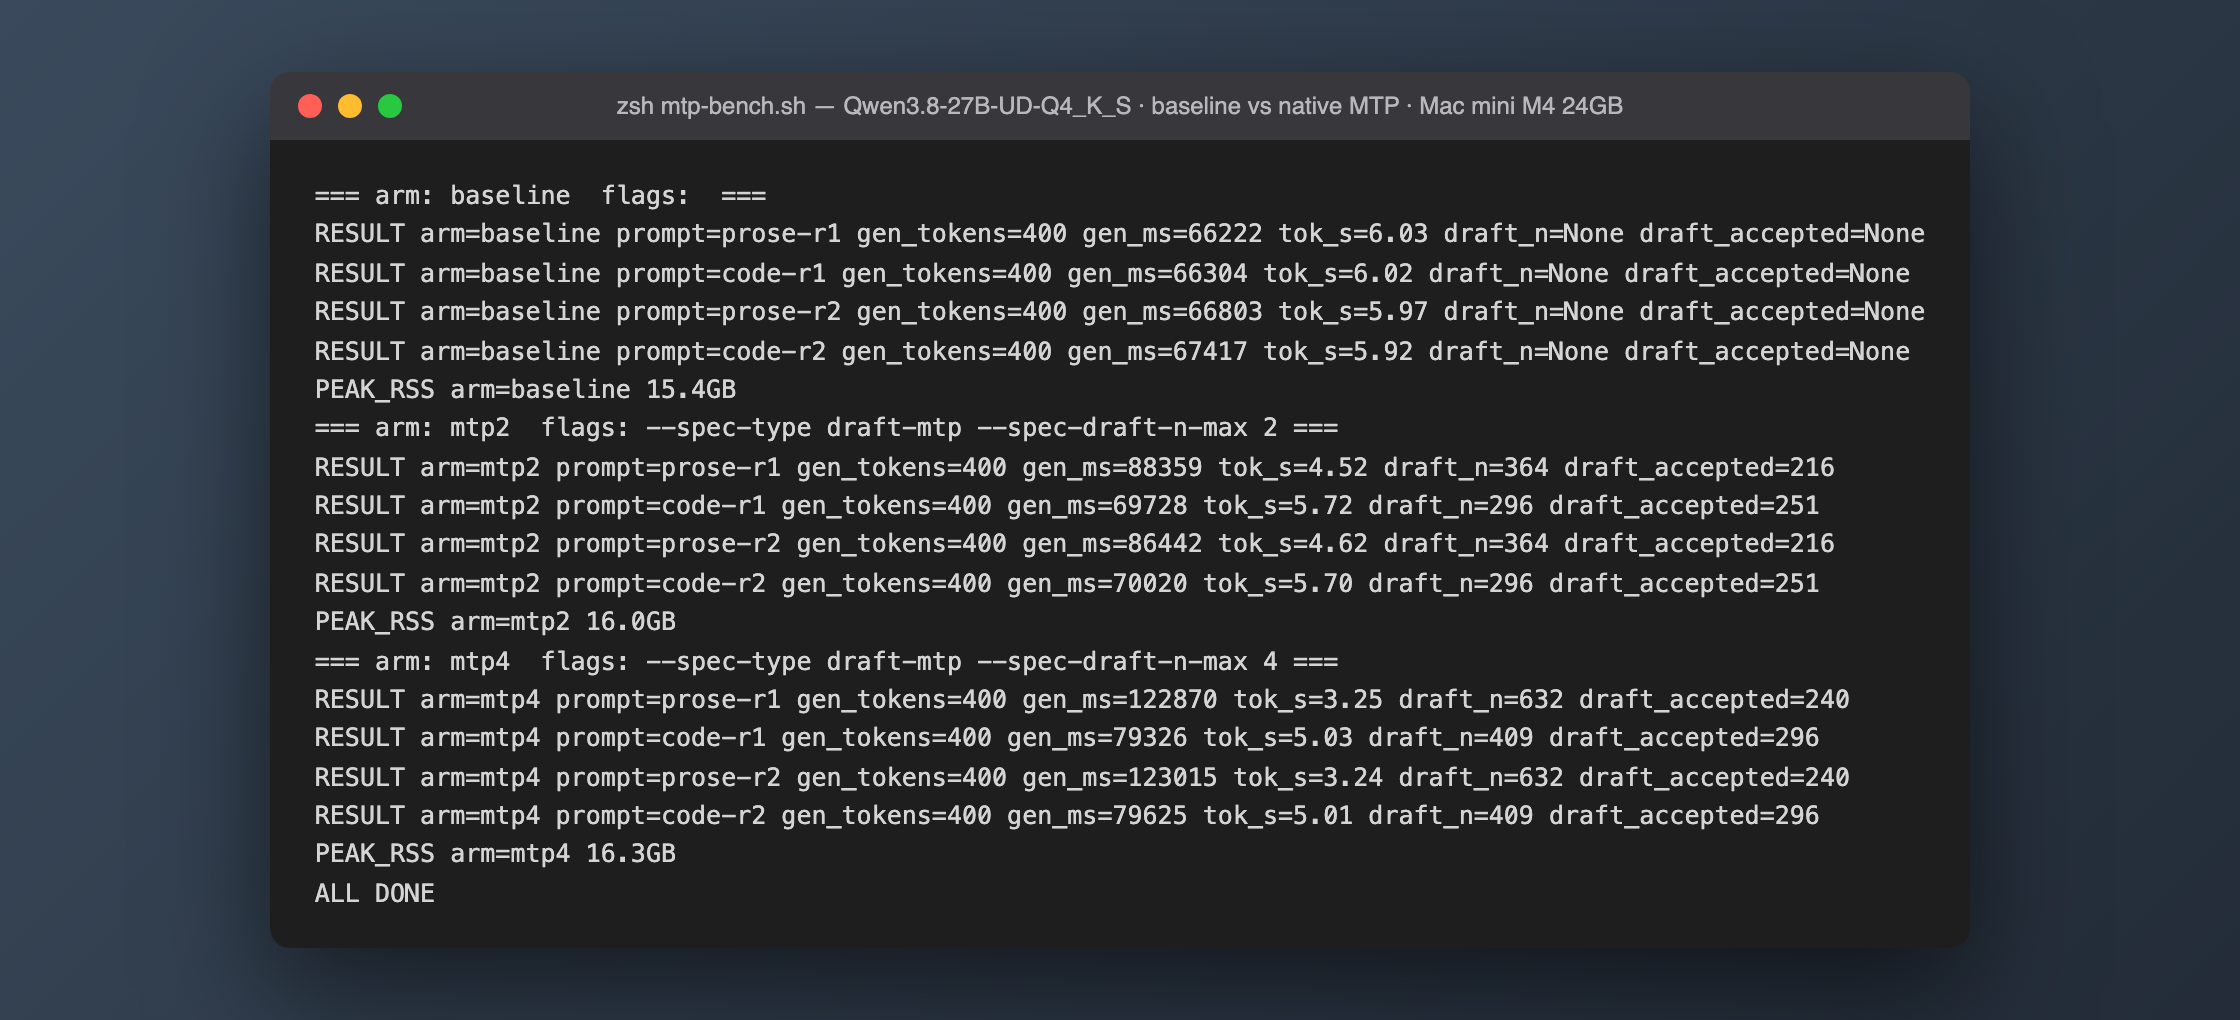
Qwen3.8 ships a trained multi-token-prediction head, and llama.cpp can mount it with one flag — no separate 2B draft model. I benchmarked it against DFlash 2 on the same 24GB Mac mini M4: memory does drop (16.0GB vs 19.4GB peak), but speed goes backwards — prose falls from 6.0 to 4.5 tok/s (-24%) while DFlash 2 delivers 1.8–1.9x on the same machine. Draft acceptance is healthy (59–85%); the loss is in Metal's verify path — batch-8 decode amortizes at just 1.13x, measured.